Some random thoughts about crypto. Notes from a course I teach. Pictures of my dachshunds.
Author: Matthew Green
I'm a cryptographer and professor at Johns Hopkins University. I've designed and analyzed cryptographic systems used in wireless networks, payment systems and digital content protection platforms. In my research I look at the various ways cryptography can be used to promote user privacy.
The other day I snarked about Trustwave’s decision to sell subordinate root (‘skeleton’) certificates to their corporate clients, for the explicit purpose of destabilizing the web’s Public Key Infrastructure ‘legitimately’* intercepting TLS connections. This practice (new to me) is ostensibly only permitted in limited, controlled settings (usuallyto spy on a company’s employees).
Trustwave argues that the key was always safe inside of a Hardware Security Module and besides, they’re not doing it any more. (Kind of like saying that you handed out the master key to every door on earth but it’s ok ’cause you chained it to a hubcap.)
Dear Certification Authority,
This note requests a set of immediate actions on your behalf, as a participant in the Mozilla root program.
Please reply by {date 2 weeks out} to confirm completion of the following actions or state when these actions will be completed.
1) Subordinate CAs chaining to CAs in Mozilla’s root program may not be used for MITM purposes, regardless of whether it is in a closed and controlled environment or not. Please review all of your subordinate CAs to make sure that they may not be used for MITM purposes. Any existing subordinate CAs that may be used for that purpose must be revoked and any corresponding HSMs destroyed by {date TBD}. For each subordinate CA that is revoked, send me: a) The certificate that signed the subCA. If it is a root certificate in NSS, then the root certificate’s subject and SHA1 fingerprint. b) The Serial Number of the revoked certificate. c) The CRL that contains the serial number of the revoked certificate.
As a CA in Mozilla’s root program you are ultimately responsible for certificates issued by you and your subordinate CAs. After {date TBD} if it is found that a subordinate CA is being used for MITM, we will remove the corresponding root certificate. Based on Mozilla’s assessment, we may also remove any of your other root certificates, and root certificates from other organizations that cross-sign your certificates.
2) Please add a statement to your CP/CPS committing that you will not issue a subordinate certificate that may be used for MITM or traffic management of domain names or IPs that the party does not legitimately own or control. Send me the URL to the updated document(s) and the impacted sections or page numbers.
…
Participation in Mozilla’s root program is at our sole discretion, and we will take whatever steps are necessary to keep our users safe. Nevertheless, we believe that the best approach to safeguard that security is to work with CAs as partners, to foster open and frank communication, and to be diligent in looking for ways to improve. Thank you for your participation in this pursuit.
Regards, Kathleen Wilson Module Owner of Mozilla’s CA Certificates Module
Now I’m no bomb-thrower, but if it were up to me, {Date TBD} would be yesterday and there would be no re-entry for the CAs caught doing this kind of thing. Still, I’m glad that Mozilla is doing this, and we’re all lucky that they have the independence and browser share to force this kind of change.
But not everything is sunshine and rainbows:
We have to trust that the CAs in question will respond honestly to Mozilla’s inquiry and will voluntarily exit a (presumably) lucrative business. This relies very much on the honor system, and it’s hard to presume much honor in a CA that would sell such a product in the first place.
Mozilla only represents 25% of the browser share, and that seems to be falling. That’s probably enough to make the difference — today — but it’d be nice to hear something similar from Microsoft or Google.
We still lack a good client-side mechanism for detecting and reporting unusual (that is: correctly signed, but inconsistent) certificates. Given the news from Trustwave, such a mechanism seems more useful than ever.
We cannot possibly have faith in the security of the Internet when CAs are willing to engage in this kind of practice — even if they do it under the most ‘carefully-controlled’ conditions.
This story has making the rounds for about a week and I’m still shocked by it. Here’s the postage stamp version: at some point in the past few years, certificate authority Trustwave basically handed out their root signing capability to a third party company. But don’t worry, it’s all better now.
As with any such story, there are bits we know and bits we have to speculate about. Speculation is more fun, so let’s start there:
Once upon a time there was a company — let’s call them ACME Inc — who really didn’t trust its employees. For ACME the solution was vigilance. Constant, invasive vigilance. ACME’s IT department was given the task of intercepting every packet sent to and from the corporate network, which seemed straightforward; until someone pointed out that they could intercept all the packets they wanted, but they couldn’t necessarily read them. Especially not the ones encrypted with SSL/TLS.
Now this isn’t a killer. ACME had a few options: they could (a) block SSL/TLS at their network gateway, forcing everyone to use cleartext connections. They could (b) force their employees to use some awkward SSL proxy. If they were feeling ambitious, they could even (c) run a man-in-the-middle on every SSL connection initiated from within their corporate network. The last option would result in some awkward certificate errors, however — which would be unpleasant for web users, and downright nasty for embedded devices or headless boxes.
But really, each of these solution is just a different version of flypaper. Why catch flies with flypaper, when you can totally screw with the trust model of the Internet?
And this is where we get to the facts. A few years back ACME — or some company like ACME — approached Trustwave with this problem. Trustwave seemed like a good group to ask, since they’re one of the select few companies that make SSL certificates, i.e., they’re one of the ‘authorities’ whose root certs are built into all of the major browsers and OSes.
Somehow the two companies cooked up the following plan. Trustwave would generate a new ‘subordinate root’ certificate with full signing authority. Anyone who possessed the signing key for this cert would essentially be Trustwave — meaning that they could vouch for any website they wanted. Of course, such a key would be enormously valuable (and dangerous). No responsible CA would allow such a thing to leave their facilities.
But apparently Trustwave’s motto is ‘think different’. So they cheerfully packed the signing key into a Hardware Security Module and sent it over to ACME. From that point on, ACME possessed the ability to transparently impersonate any SSL website on the Internet.
And impersonate they did; whenever some client initiated an SSL connection from within ACME’s corporate network, an ACME server would intercept the connection, sign a fresh certificate on the requested domain, then deliver that cert back to the client. To the client, it appeared that the connection went through perfectly. But of course the client was now talking to ACME’s server, not to the company whose name was on the certificate. ACME would in turn connect on to the target SSL server, thus completing the connection.
Technically this tampering wasn’t totally invisible; a clever user might notice that every certificate was now signed by Trustwave — and comparison with certificates received outside of ACME’s network would clearly reveal something funny going on. But since the vast majority of web users don’t check this kind of thing, the interception was basically transparent.
Now I hope I don’t need to tell you why this is a bad idea. Let’s just take it a a given that this is a bad idea. Even Trustwave now realizes it’s a bad idea, and have ‘proactively’ revoked the cert to make sure the evil thing doesn’t fall into the wrong hands. From their blog post about it:
Trustwave has decided to be open about this decision as well as stating that we will no longer enable systems of this type and are effectively ending this short journey into this type of offering.
I guess we can at least be thankful that Trustwave has decided to be open about this decision, despite the fact that they weren’t open about it while it was happening. Let’s all hope this is really the last journey Trustwave plans to take into this type of offering, where by ‘offering’ I mean — disastrous, short-sighted mistake.
I adhere to a ‘one post, one topic’ rule on this blog, which means that this weekend I actually have to choose which bad-crypto news I’m going to blog about.
It’s a tough call, but the most interesting story comes via Erik Tews, who recently attended a talk on satellite phone security at Ruhr Universität Bochum. It seems that researchers Benedikt Driessen, Ralf Hund, Carsten Willems, Christof Paar, and Thorsten Holz have reverse-engineered and cryptanalyzedtheproprietary ciphers used in the GMR-1 and GMR-2 satellite telephone standards.* If you’ve never heard of these standards, what you need to know is that they power the networks of satphone providers Thuraya and Inmarsat.
The verdict? Encrypting with these ciphers is better than using no encryption. But not necessarily by much.
I guess this shouldn’t come as a big shock — link privacy in mobile telephony has always been kind of a mess. And the GMR ciphers come from the same folks (ETSI) who brought us the A5-series GSM ciphers. If you pay attention to this sort of thing, you probably know that those ciphers have also had some problems. In fact, today it’s possible to download rainbow tables that permit (efficient) decryption of A5/1-encrypted GSM phone calls.
A5/1 is actually the strong member of the GSM family. For export purposes there’s A5/2 — a weakened version with a much shorter key. You don’t hear about people downloading huge A5/2 rainbow tables, mostly because you don’tneedthem. A5/2 is vulnerable to ciphertext-only attacks that run in a few minutes on a standard PC.
ETSI seems to have had A5/2 in mind when developing the GMR-1 and GMR-2 ciphers. Both are custom designs, use short keys, and depend heavily on obscurity of design to make up for any shortcomings (the ciphers are only given to manufacturerswho sign an NDA). This secrecy hardly inspires confidence, and worse yet, it doesn’t even do a good job of keeping things secret. The R.U.B. researchers didn’t have to break into Thuraya’s hardware lab; they simply reversed the ciphers from handsetfirmware updates.**
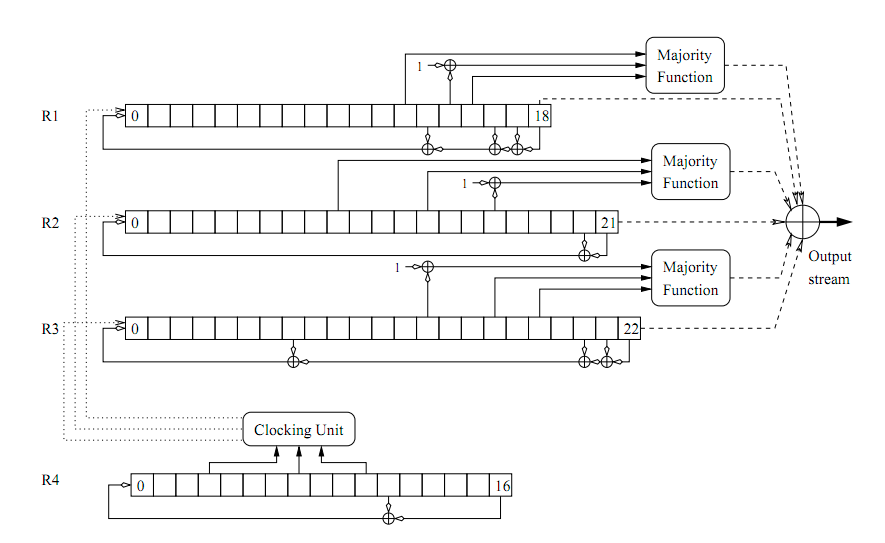
GMR-1 uses an LFSR-based cipher quite similar to A5/2 (pictured above), which means that it’s vulnerable to a similar class of attacks. Since the underlying plaintext has correctness checks built into it, it’s possible to recover the key using only ciphertext and about 30 minutes on a standard PC. The GMR-2 cipher is a bit more sophisticated (and weirder to boot), but it also appears to have weaknesses.
So why is this a big deal? The obvious answer is that satellite telephone security matters. In many underdeveloped rural areas it’s the primary means of communicating with the outside world. Satphone coverage is also important in war zones, where signal privacy is of more than academic interest.
Moreover, eavesdropping on satellite communications is (in principle) easier than eavesdropping on cellular signals. That’s because satellite ‘spot beams’ cover relatively broad geographic territories (Thuraya’s are 600km on average). So you don’t just have to worry about eavesdropping by your neighbor, you have to worry about eavesdropping by neighboring countries.
The really sad thing is that, unlike cellular networks — which are fundamentally vulnerable to government eavesdropping at the infrastructure level — satellite networks like Thuraya/Inmarsat don’t need local infrastructure. That means their systems really could have provided privacy for individuals persecuted by oppressive regimes. You can argue about whether the manufacturers even had the option to use strong ciphers; it’s quite possible they didn’t. Still, I suspect this will be cold comfort to those who suffer as a direct result of ETSI’s design choices.
Those who are really in the know (news organizations, for example) claim to use additional security measures beyond the built-in link encryption found in GMR-1 and GMR-2. Presumably these days the best way to do that is to run your own voice protocol via the packet data extensions. This practice ought to become more common going forward; now that the GMR-1 code is public, it looks like the barriers to eavesdropping are going to go down quite a bit.
* Update2/16/2012: I had some initial confusion about the authorship on this work, but the research paper clears it all up: see here.
** And by ‘simply’, I mean ‘with great expertise and difficulty’ — don’t read this as trivializing the effort involved. Obtaining the ciphers meant disassembling code written in a proprietary DSP instruction set, and then searching for a cipher without knowing exactly what it looks like. All in all a pretty significant accomplishment. The point here is that it could have been a lot harder. If you’re going to keep a cipher secret, you shouldn’t release it as software in the first place.
While browsing some community websites, I noticed a few people talking about the security of double (or more generally, multiple) encryption. Multiple encryption addresses the following problem: you have two (or more) encryption schemes, and you’re worried that one of them might get compromised. Surely if you encrypt with both at the same time you’ll buy yourself an added safety margin.
Let me preface this by saying that multiple encryption addresses a problem that mostly doesn’t exist. Modern ciphers rarely get broken — at least, not in the Swordfish sense. You’re far more likely to get hit by malware or an implementation bug than you are to suffer from a catastrophic attack on AES.*
That said, you really are likely to get hit by malware or an implementation bug. And that’s at least one argument for multiple encryption — if you’re willing to encrypt on separate, heterogenous devices.** There’s also the future to think about. We feel good about AES today, but how will we feel in 2040?
I note that these are problems for the extremely paranoid — governments, mostly — not for the typical developer. The majority of us should work on getting single encryption right. But this kind of thing isn’t ridiculous — the NESSIE standards even recommend it. Moreover, my experience is that when people start asking questions about the security of X, it means that they’re already doing X, and have been for some time.
So for all that, it’s worth answering some of these questions. And roughly speaking, the questions are:
Am I better off encrypting with two or more encryption schemes (or keys?)
Could I be worse off?
If I have to do it, how should I do it securely?
Given how little sleep I’ve gotten recently I don’t promise to answer these fully, or in any particular order. But I do hope I can provide a little bit of insight around the edges.
Preliminaries
There are many ways to double encrypt, but for most people ‘double encryption’ means this:
SuperDuperEncrypt(KA, KB, M) = EncryptA(KA, EncryptB(KB, M))
This construction is called a cascade. Sometimes EncryptA and EncryptB are different algorithms, but that’s not really critical. What does matter for our purposes is that the keysKA and KB are independently-generated.*** (To make life easier, we’ll also assume that the algorithms are published.)A lot has been written about cascade encryption, some good and some bad. The answer to the question largely depends on whether the algorithms are simply block ciphers, or if they’re true encryption algorithms (e.g., a mode of operation using a block cipher). It also depends on what security definition you’re trying to achieve.
The good
Let’s consider the positive results first. If either EncryptA or EncryptB is ‘semantically secure’, i.e., indistinguishable under chosen-plaintext attack, then so is the cascade of the two. This may seem wonky, but it’s actually very handy — since many common cryptosystems are specifically analyzed under (at least) this level of security. For example, in the symmetric setting, both CBC and CTR modes of operation can both be shown to achieve this security level, provided that they’re implemented with a secure block cipher.
So how do we know the combined construction is secure? A formal proof can be found in this 2002 paper by Herzberg, but the intuition is pretty simple. If there’s an attack algorithm that ‘breaks’ the combined construction, then we can use that algorithmto attack either of the two underlying algorithms by simply picking our own key for the other algorithm and simulating the double encryption on its ciphertexts.
This means that an attack on the combination is an attack on the underlying schemes. So if one is secure, you’re in good shape.
The not-so-good
Interestingly, Herzberg also shows that the above result does not apply for all definitions of security, particularly strong definitions such as adaptive-chosen ciphertext security. In the symmetric world, we usually achieve this level of security using authenticated encryption.
To give a concrete (symmetric encryption) example, imagine that the inner layer of encryption (EncryptB) is authenticated, as is the case in GCM-mode. Authenticated encryption provides both confidentiality (attackers can’t read your message) and authenticity (attackers can’t tamper with your message — or change the ciphertext in any way.)
Now imagine that the outer scheme (EncryptA) doesn’t provide this guarantee. For a simple example, consider CBC-mode encryption with padding at the end. CBC-mode is well known for its malleability; attackers can flip bits in a ciphertext, which causes predictable changes to the underlying plaintext.
The combined scheme still provides some authenticity protections — if the attacker’s tampering affects the inner (GCM) ciphertext, then his changes should be detected (and rejected) upon combined decryption. But if his modifications only change the CBC-mode padding, then the combined ciphertext could be accepted as valid. Hence the combined scheme is ‘benignly’ malleable,making it technically weaker than the inner layer of encryption.
Do you care about this? Maybe, maybe not. Some protocols really do require a completely non-malleable ciphertext — for example, to prevent replay attacks — but in most applications these attacks aren’t world-shattering. If you do care, you can find some alternative constructions here.
The ugly
Of course, so far all I’ve discussed is whether the combined encryption scheme is at least as secure as either underlying algorithm. But some people want more than ‘at least as’. More importantly, I’ve been talking about entire encryption algorithms (e.g., modes of operation), not raw ciphers.
So let’s address the first question. Is a combined encryption scheme significantly more secure than either algorithm on its own? Unfortunately the answer is: not necessarily. There are at least a couple of counterexamples here:
The encryption scheme is a group. Imagine that EncryptA and EncryptB are the same algorithm, with the following special property: when you encrypt sequentially with KA and KB you obtain a ciphertext that can be decrypted with some third key KC.**** In this case, the resulting ciphertext ought to be at least as vulnerable as a single-encrypted ciphertext. Hence double-encrypting gives you no additional security at all. Fortunately modern block ciphersdon’t (seem) to have this property — in fact, cryptographers explicitly design against it, as it can make the cipher weaker. But some number-theoretic schemes do, hence it’s worth looking out for.
Meet-in-the-Middle Attacks. MiTM attacks are the most common ‘real-world’ counterexample that come up in discussions of cascade encryption (really, cascade encipherment). This attack was first discovered by Diffie and Hellman, and is a member of a class we call time-space tradeoff attacks. It’s useful in constructions that use a deterministic algorithm like a block cipher. For example:DOUBLE_DES(KA, KB, M) = DES_ENCRYPT(KA, DES_ENCRYPT(KB, M))
On the face of it, you’d assume that this construction would be substantially stronger than a single layer of DES. If a brute-force attack on DES requires 2^56 operations (DES has a 56-bit key), you’d hope that attacking a construction with two DES keys would require on the order of 2^112 operations. But actually this hope is a false one — if the attacker has lots of storage.
The attack works like this. First, obtain the encryption C of some known plaintext M under the two unknown secret keys KA and KB. Next, construct a huge table comprising the encipherment of M under every possible DES key. In our DES example there are 2^56 keys, this would take a corresponding amount of effort, and the resulting table will be astonishingly huge. But leave that aside for the moment.
Finally, try decrypting C with every possible DES key. For each result, check to see if it’s in the table you just made. If you find a match, you’ve now got two keys: KA’ and KB’ that satisfy the encryption equation above.*****
If you ignore storage costs (ridiculously impractical, but which may also be traded for time), this attack will run you (2^56)*2 = 2^57 cipher operations. That’s much less than the 2^112 we were hoping for. If you’re willing to treat it as a chosenplaintext attack you can even re-use the table for many separate attacks.
Plaintext distribution issues. Maurer showed one more interesting result, which is that in a cascade of ciphers, the entire construction is guaranteed to be as secure as the first cipher, but not necessarily any stronger. This is because the first cipher may introduce certain patterns into its output that can assist the attacker in breaking the second layer of encipherment. Maurer even provides a (very contrived) counterexample in which this happens.
I presume that this is the source of the following folklore construction, which is referenced in Applied Cryptography and other sources around the Internet:UberSuperEncrypt(KA, KB, M) = EncryptA(KA, R⊕M) || EncryptB(KB, R))
Where || indicates concatenation, and R is a random string of the same length of the message. Since in this case both R and R⊕M both have a random distribution, this tends to eliminate the issue that Maurer notes. At the cost of doubling the ciphertext size!
Now the good news is that multiple encipherment (done properly) can probably make things more secure. This is precisely what constructions like DESX and 3DES try to achieve (using a single cipher). If you make certain strong assumptions about the strength of the cipher, it is possible to show that these constructions are harder to attack than the underlying cipher itself (see this analysis of DESX and this one of 3DES).
I warn you that these analyses use an unrealistic model for the security of the cipher, and they don’t treat multiple distinct ciphers., Still, they’re a useful guide — assuming that your attacker does not have any special attack against (at least one) of the underlying schemes. Your mileage may vary, and I would generally advise against assembling this sort of thing yourself unless you really know what you’re doing.
In summary
I’m afraid this post will end with a whimper rather than a bang. It’s entirely possible to combine encryption schemes in secure ways (many of which are not cascade constructions), but the amount of extra security you’ll get is subject to some debate.
In fact, this entire idea has been studied for a quite a while under the heading of (robust) combiners. These deal with combining cryptosystems (encryption, as well as hashing, signing, protocols, etc.) in a secure way, such that the combination remains secure even if some of the underlying schemes are broken.
If you’re interested, that’s the place to start. But in general my advice is that this is not something that most people should spend a lot of time doing, outside of (perhaps) the government and the academic world. If you want to do this, you should familiarize yourself with some of the academic papers already mentioned. Otherwise, think hard about why you’re doing it, and what it’s going to buy you.
Notes:
* And yes, I know about MD5 and the recent biclique attacks one AES. That still doesn’t change my opinion.
** Note that this is mostly something the government likes to think about, namely: how to use consumer off-the-shelf products together so as to achieve the same security as trusted, government-certified hardware. I’m dubious about this strategy based on my suspicion that all consumer products will soon be manufactured by Foxconn. Nonetheless I wish them luck.
*** This key independence is a big deal. If the keys are related (worst case: KA equals KB) then all guarantees are off. For example, consider a stream cipher like CTR mode, where encryption and decryption are the same algorithm. If you use the same algorithm and key, you’d completely cancel out the encryption, i.e.:CTR_ENC(K, IV, CTR_ENC(K, IV, M) = M.
**** Classical substitution ciphers (including the Vigenere cipher and Vernam One-Time Pad) have this structure.
***** The resulting KA’ and KB’ aren’t necessarily the right keys, however, due to false positives: keys that (for a single message M) satisfy DES(KA’, DES(KB’, M)) = DES(KA, DES(KB, M)). You can quickly eliminate the bad keys by obtaining the encryption of a second message M’ and testing it against each of your candidate matches. The chance that a given false positive will work on two messages is usually quite low.
Hackers are paler than the general public. Also, they use gel.
I was just working on an honest-to-god technical post when I thought: here’s an idea, let’s illustrate this point with a reference to the classic bad-security movie ‘Swordfish‘. What a terrible mistake.
In searching for a link I turned up what purports to be Skip Woods’ original shooting script. And now I’m not going to get any work done until I get this off my chest: holy &#^$*&# crap the cryptography in that movie is way worse than I thought it was.
I know, I know, it’s a ten year old movie and it’s all been said before. So many times that it’s not even shooting fish in a barrel anymore, it’s more like shooting frozen fish in a barrel.
There isn’t much crypto in the movie. But what there is, whew… If you consider a modified Pritchard scale where the X axis is ‘refers to a technology that could actually exist‘ and the Y axis is ‘doesn’t make me want to stab myself’, Skip Woods has veered substantially into negative territory.
I know most people will say something like ‘Duh’ or ‘It’s swordfish!’ or ‘What do you expect from a movie where a guy breaks a password while John Travolta holds a gun to his head and Halle Berry fiddles around in his lap.’And yes, I realize that this happens. But that stuff actually doesn’t trouble me so much.
What does bother me is that the DoD system he breaks into uses 128-bit RSA encryption. Does anyone really think that the NSA would validate that? And then there’s this exchange (emphasis mine):
                            GABRIEL
                  Here's the deal. I need a worm,
                  Stanley. A hydra, actually. A
                  multi-headed worm to break an
                  encryption and then sniff out
                  latent digital footprints
                  throughout an encrypted network.

                                STANLEY
                  What kind of cypher?

                                GABRIEL
                  Vernam encryption.

                                STANLEY
                  A Vernam's impossible. Its key
                  code is destroyed upon
                  implementation. Not to mention
                  being a true 128 bit encryption.

                                GABRIEL
                  Actually, we're talking 512 bit.
Ok, I don’t know about the stuff at the beginning — but the rest is serious. We’re not going after a mere Vernam One-Time Pad, which would just be impossible to break. Instead we’re going after the Big Kahuna, the true 128-bit unbreakable Vernam One-Time Pad. No, wait, that’s too easy. To do this right, we’re gonna have to break the full 512-bit unbreakable Vernam One-Time Pad, which is at least 2^384 times as unbreakable as the regular unbreakable kind. Get Halle back in here!
What kills me is that if you squint a little some of this technical jargon kind of makes sense. This can only mean one thing: Skip Woods brought in a technical advisor. But having done so, he obviously took the advice he was given and let it fly prettily out the windows of his Mercedes on the way home. Then he wrote what he wanted to write. Who needs an unbreakable cipher when we can have an unbreakable cipher with a frickin’ 128 512 bit key!
I thought this post would be cathartic, but the truth is I just feel dirty now. Where will this end? Will I find myself criticizing Mercury Rising and Star Trek? The thing is, I like movies, even bad ones. I don’t ask for realism. I just have limits.
And Swordfish is a bridge too far. If you’re a Hollywood type and you need someone to vet your scripts, I’ll do it. Cheap. I won’t leave you all hung up in painful details — if your plot requirements have the main character breaking cryptography in his head, I’ll find a way to make it work. But it won’t be a One-Time Pad and it sure as hell won’t be 128-bit RSA. It will be *ahem* realistic.
Here’s a fascinating post by Tim Wilde overat the Tor Project blog, discussing China’s growing sophistication in blocking Tor connections:
In October 2011, ticket #4185 was filed in the Tor bug tracker by a user in China who found that their connections to US-based Tor bridge relays were being regularly cut off after a very short period of time. At the time we performed some basic experimentation and discovered that Chinese IPs (presumably at the behest of the Great Firewall of China, or GFW) would reach out to the US-based bridge and connect to it shortly after the Tor user in China connected, and, if successful, shortly thereafter the connection would be blocked by the GFW.
… we discovered two types of probing. First, “garbage binary” probes, containing nothing more than arbitrary (but sometimes repeated in later probes) binary data, were experienced by the non-China side of any connection that originated from China to TCP port 443 (HTTPS) in which an SSL negotiation was performed. … The purpose of these probes is unknown …
The second type of probe, on the other hand, is aimed quite directly at Tor. When a Tor client within China connected to a US-based bridge relay, we consistently found that at the next round 15 minute interval (HH:00, HH:15, HH:30, HH:45), the bridge relay would receive a probe from hosts within China that not only established a TCP connection, but performed an SSL negotiation, an SSL renegotiation, and then spoke the Tor protocol sufficiently to build a one-hop circuit and send a BEGIN_DIR cell. No matter what TCP port the bridge was listening on, once a Tor client from China connected, within 3 minutes of the next 15 minute interval we saw a series of probes including at least one connection speaking the Tor protocol.
Obviously this is disturbing. And unlike previous, passive efforts to block Tor, these active attacks are tough to defend against. After all, Tor was designed to be a public service. If the general public can download a Tor client and connect to a bridge, so can the Chinese government. This means that protocol-level workarounds (obfuscators, for example) will only work until China cares enough to stop them.
The situation isn’t hopeless: proposed workarounds include password protecting Tor bridges, which might solve the problem to an extent — though it seems to me that this is just kicking the problem down the road a bit. As with the bridge security model, it embeds the assumption that Chinese users can find bridges/passwords, but their government can’t. More to the point, any password protocol is going to have to work hard to look ‘innocent’ (i.e., not Tor-like) to someone who doesn’t know the password. There are a lot of ways this could go wrong.
On the research side there are ideas like Telex which would eliminate the need for bridges by embedding anti-censorship into the network. Chinese Tor clients would make TLS connections to arbitrary US websites; the connections would be monitored by special Telex routers along the way; any TLS connection with a special steganographic marking would get transparently re-routed to the nearest Tor node. Unfortunately, while the crypto in Telex is great, actually deploying it would be a nightmare — and would almost certainly require government cooperation. Even if Western governments were game, the Chinese government could respond by banning overseas TLS connections altogether.
One last note: I love a good mystery, so does anyone care to speculate about those “garbage probes”? What are they — a test? Automated fuzzing? Most likely they’re an attempt to provoke a response from some other TLS server that the Chinese government cares about, but if it’s not Tor then what is it?
Update 1/26: Emily Stark points me to the Flash Proxies project out of Stanford. This would put Tor proxies in individual client machines, thus massively increasing the number of bridges available and eliminating the outgoing client->bridge connection. They even have an implementation, though I warn you: running untrusted traffic through your Flash plugin is not for the faint of heart!
Last week the students and I went looking for our long-lost GnuRadio USRP in a dusty hardware security lab down the hall. This particular USRP hasn’t been seen in about five years (I suspect it may have been deported with the lab’s previous occupant) so the whole thing was kind of a long shot.
Sometimes best part of a treasure hunt is what you find along the way. The students didn’t find the USRP, but they did uncover a fog machine and laser that someone had tucked under a workbench. This kept them happy ’til we got a whiff of the “fog” it was making. I scored something even better: a mint copy of Tim Hartnell‘s 1985 masterpiece, the Giant Book of Computer Games.
If you’re just a few years younger than me, you might think Games is a book about games. But of course, it literally is games: dozens of all-caps BASIC listings, printed in a font that was probably old when Wargames was new. Each game sits there on the page, pregnant with potential, waiting for a bored 9-year old to tap it into his C64 or Apple ][ and hit “RUN”. (Sadly, this could be a long wait.)
Flipping through Games brings back memories. The Chess AI was a bastard, routinely cheating even if you implemented it properly. And you never implemented anything properly, at least not on the first pass. This was part of the fun. Between typos and the fact that Hartnell apparently coded to his own BASIC standard, the first play usually went like this:
WELCOME TO SNARK HUNTENTER 1 FOR SNARK, 2 FOR HUNTER> 2YOU CHOSE SNARK?SYNTAX ERROR AT LINE 3980READY
You learned debugging fast. When that didn’t work, your last, desperate move was simply to delete the offending lines — ’til the program either (a) worked, or (b) got so crazy that you deleted it and loaded Bruce Lee off a cassette. Sometimes you hit the sweet spot between the two: my “Chess” AI would grab control of my pieces Agent Smith-style and send them hurtling towards my undefended King. I never saw this as a bug, though; I just thought it had style.
When I started writing this post I intended to make a broader point about how my experience with Games mirrors the way that modern implementers feel when faced with a mysterious, unjustified cryptographic standard. I think there is a point to be made here, and I’ll make it. Another day.
But when I googled to see what Hartnell is up to, I was saddened to learn that he died all the way back in 1991, only a few years after Games was published. He was only a few years older than I am today. So on reflection, I think I’ll just let this post stand as it is, and I’ll go spend some time with my kid.
Tim, wherever you are, please accept this belated tribute. Your book meant a lot to me.
A few weeks back I found myself on the wrong side of Daniel Bernstein over something I’d tweeted the week before.This was pretty surprising, since my original tweet hadn’t seemed all that controversial.
What I’d said was that cryptographic standards aren’t always perfect, but non-standard crypto is almost always worse. Daniel politely pointed out that I was nuts — plenty of bad stuff appears in standards, and conversely, plenty of good stuff isn’t standardized. (As you can see, the conversation got a little weirder after that.)
Today I’m here to say that I’ve found religion. Not only do I see where Daniel’s coming from, I’m here to surrender, throw down my hat and concede defeat. Daniel: you win. I still think standards are preferable in theory, but only if they’re promulgated by reasonable standards bodies. And we seem to have a shortage of those.
My new convictions are apropos of an innocuous-looking ePrint just posted by Kazuhiko Minematsu, Hiraku Morita and Tetsu Iwata. These researchers have found serious flaws in an authenticated block cipher mode of operation called EAX’ (henceforth: EAXprime). EAXprime was recently adopted as the encryption mode for ANSI’s Smart Grid standard, and (until today) was practically a shoo-in to become a standalone NIST-certified mode of operation.
Ok, so standards get broken. Why I am I making such a big deal about this one? The simple reason is that EAXprime isn’t just another standard. It’s a slightly-modified version of EAX mode, which was proposed by Bellare, Rogaway and Wagner. And the important thing to know about EAX (non-prime) is that it comes with a formal proof of security.
It’s hard to explain how wonderful this is. The existence of such a proof means that (within limits) a vulnerability in EAX mode would indicate a problem with the underlying cipher (e.g., AES) itself. Since we’re pretty confident in the security of our standard block ciphers, we can extend that confidence to EAX. And the best part: this wonderful guarantee costs us almost nothing — EAX is a very efficient mode of operation.
But not efficient enough for ANSI, which decided to standardize on a variant called EAXprime. EAXprime is faster: it uses 3-5 fewer block cipher calls to encrypt each message, and (in the case of AES) about 40 bytes less RAM to store scheduled keys. (This is presumably important when your target is a tiny little embedded chip in a smart meter.)
Unfortunately, there’s a cost to that extra speed: EAXprime is no longer covered by the original EAX security proof. Which brings us towards the moral of the story, and to the Minematsu, Morita and Iwata paper.
Did you ever see that old episode of Knight Rider where the bad guys figure out how to neutralize KITT‘s bulletproof coating? Reading this paper is kind of like watching the middle part of that episode. Everything pretty much looks the same but holy crap WTF the bullets aren’t bouncing off anymore.
The MMI attacks allow an adversary to create ciphertexts (aka forgeries) that seem valid even though they weren’t created by the actual encryptor. They’re very powerful in that sense, but they’re limited in others (they only work against very short messages). Still, at the end of the day, they’re attacks. Attacks that couldn’t possibly exist if the standards designers had placed a high value on EAX’s security proof, and had tried to maintain that security in their optimized standard.
And this is why I’m admitting defeat on this whole standards thing. How can I advocate for crypto standards when standards bodies will casually throw away something as wonderful as a security proof? At least when KITT lost his bulletproof coating it was because of something the bad guys did to him. Can you imagine the good guys doing that to him on purpose?
Over the past few weeks I’ve been scouring the Internet for a good list of crypto and security resources to link to from this blog. The ideal list would include technical blogs, of course, but also textbooks, courses and other helpful websites.
There are a few good resource lists out on the web. Some are even pretty good, but none of them meet all of my criteria. Per XKCD, I decided that the solution here is to obviate them all and create an even better list of my own. You can see my first draft here (it’s also linked from the sidebar at right, under ‘Useful crypto resources‘). This is very much a work in progress, and I hope that you’ll all help me to flesh it out.
There’s just one problem: the paper doesn’t seem to be online yet (Update 1/10:It is now. See my update further below.) Infoworld has a few vague details, and it looks like the vulnerability fixes are coming fast and furious. So let’s put on our thinking caps and try to puzzle this one out.
What is Datagram TLS?
If you’re reading this blog, I assume you know TLS is the go-to protocol for encrypting data over the Internet. Most people associate TLS with reliable transport mechanisms such as TCP. But TCP isn’t the only game in town.
Audio/video streaming, gaming, and VoIP apps often use unreliable datagram transports like UDP. These applications don’t care if packets arrive out of order, or if they don’t arrive at all. The biggest priority is quickly handling the packets that do arrive.
Since these applications need security too, TLS tries to handle them via an extension called Datagram TLS (DTLS). DTLS addresses the two big limitations that make TLS hard to use on an unreliable datagram transport:
TLS handshake messages need to arrive whole and in the right order. This is easy when you’re using TCP, but doesn’t work so well with unreliable datagram transport. Moreover, these messages are bigger than the typical 1500 byte Ethernet frame, which means fragmentation (at best), and packet loss (at worst).
Ordinarily TLS decryptionassumes that you’ve received all the previous data. But datagrams arrive when they want to — that means you need the ability to decrypt a packet even if you haven’t received its predecessor.
There are various ways to deal with these problems; DTLS mounts a frontal assault. The handshake is made reliable by implementing a custom ack/re-transmit framework. A protocol-level fragmentation mechanism is added to break large handshake messages up over multiple datagrams. And most importantly: the approach to encrypting records is slightly modified.
So what’s the problem?
To avoid radical changes, DTLS inherits most of the features of TLS. That includes its wonky (and obsolete) MAC-then-Encrypt approach to protecting data records. Encryption involves three steps:
Append a MAC to the plaintext to prevent tampering.
Pad the resulting message to a multiple of the cipher block size (16 bytes for AES). This is done by appending X bytes of padding, where each byte must contain the value X.
Cryptographers have long known that this kind of encryption can admit padding oracle attacks. This happens when a decryptor does something obvious (throw an error, for example) when it encounters invalidpadding, i.e., padding that doesn’t meet the specification above.
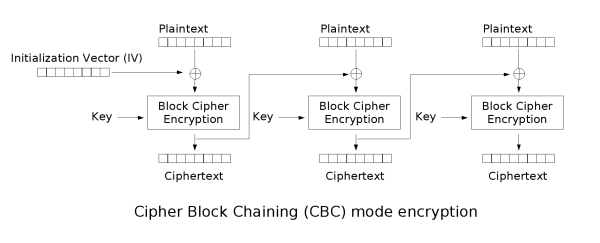
CBC Mode encryption, courtesy Wikipedia.
This wouldn’t matter very much, except that CBC mode is malleable. This means an attacker can flip bits in an intercepted ciphertext, which will cause the same bits to be flipped when the ciphertext is ultimately decrypted. Padding oracle attacks work by carefully tweaking a ciphertext in specific ways before sending it to an honest decryptor. If the the decryptor returns a padding error, then the adversary knows something about the underlying plaintext. Given enough time the attacker can use these errors to completely decrypt the message.
I could spend a lot of time describing padding oracle attacks, but it’s mostly beside the point.** Standard TLS implementations know about this attack and deal with it in a pretty effective way. Whenever the decryptor encounters bad padding, it just pretends that it hasn’t. Instead, it goes ahead with the rest of the decryption procedure (i.e., checking the MAC) even if it knows that the message is already borked.
This is extra work, but it’s extra work with a purpose. If a decryptor doesn’t perform the extra steps, then messages with bad padding will get rejected considerably faster than other messages. A clever attacker can detect this condition by carefully timing the responses. Performing the unnecessary steps (mostly) neutralizes that threat.
Ok, so you say these attacks are already mitigated. Why are we still talking about this?
Before I go on, I offer one caveat: what I know about this attack comes from speculation, code diffs and some funny shapes I saw in the clouds this afternoon. I think what I’m saying is legit, but I won’t swear to it until I read Alfardan and Paterson’s paper.
But taking my best guess, there are two problems here. One is related to the DTLS spec, and the second is just an implementation problem. Either one alone probably wouldn’t be an issue; the two together spell big trouble.
The first issue is in the way that the DTLS spec deals with invalid records. Since standard TLS works over a reliable connection, the application should never receive invalid or out-of-order data except when packets are being deliberately tampered with. So when standard TLS encounters a bad record MAC (or padding) it takes things very seriously — in fact, it’s required to drop the connection.
This necessitates a new handshake, a new key, and generally makes it hard for attackers to run an honest padding oracle attack, since these attacks typically require hundreds or thousands of decryption attempts on a single key.***
DTLS, on the other hand, runs over an unreliable datagram transport, which may not correct for accidental packet errors. Dropping the connection for every corrupted packet just isn’t an option. Thus, the standard is relaxed. An invalid MAC (or padding) will cause a single record to be thrown away, but the connection itself goes on.
This still wouldn’t matter much if it wasn’t for the second problem, which is specific to the implementation of DTLS in libraries like OpenSSL and GnuTLS.
You see, padding oracle vulnerabilities in standard TLS are understood and mitigated. In OpenSSL, for example, the main decryption code has been carefully vetted. It does not return specific padding errors, and to avoid timing attacks it performs the same (unnecessary) operations whether or not the padding checks out.
In a perfect world DTLS decryption would do all the same things. But DTLS encryption is subtly different from standard TLS encryption, which means it’s implemented in separate code. Code that isn’t used frequently, and doesn’t receive the same level of scrutiny as the main TLS code. Thus — two nearly identical implementations, subject to the same attacks, with one secure and one not. (Update 1/11: There’s a decent explanation for this, see my update below.)
And if you’re the kind of person who needs this all tied up with a bow, I would point you to this small chunk of the diff just released for the latest OpenSSL fix. It comes from the DTLS-specific file d1_pkt.c:
+ /* To minimize information leaked via timing, we will always+ * perform all computations before discarding the message.+ */
+ decryption_failed_or_bad_record_mac = 1;
I guess that confirms the OpenSSL vulnerability. Presumably with these fixes in place, the MAC-then-Encrypt usage in DTLS will now go back to being, well, just theoretically insecure. But not actively so.
Update 1/11/2012: Kenny Paterson has kindly sent me a link to the paper, which wasn’t available when I wrote the original post. And it turns out that while the vulnerability is along the lines above, the attack is much more interesting.
An important aspect that I’d missed is that DTLS does not return error messages when it encounters invalid padding — it just silently drops the packet. This helps to explain the lack of countermeasures in the DTLS code, since the lack of responses would seem to be a padding oracle attack killer.
Alfardan and Paterson show that this isn’t the case. They’re able to get the same information by timing the arrival of ‘heartbeat’ messages (or any predictable responses sent by an upper-level protocol). Since DTLS decryption gums up the works, it can slightly delay the arrival of these packets. By measuring this ‘gumming’ they can determine whether padding errors have ocurred. Even better, they can amplify this gumming by sending ‘trains’ of valid or invalid packets.
All in all, a very clever attack. So clever, in fact, that it makes me despair that we’ll ever have truly secure systems. I guess I’ll have to be satisfied with one less insecure one.
Notes:
* N.J.A. Alfardan and K.G. Paterson, Plaintext-Recovery Attacks Against Datagram TLS, To appear in NDSS 2012.
** See here for one explanation. See also a post from this blog describing a padding oracle attack on XML encryption.
*** There is one very challenging padding oracle attack on standard TLS (also mitigated by current implementations). This deals with the problem of session drops/renegotiation by attacking data that remains constant across sessions — things like passwords or cookies.
 subordinate root (‘skeleton’) certificates to their corporate clients, for the explicit purpose of destabilizing the web’s Public Key Infrastructure ‘legitimately’* intercepting TLS connections. This practice (new to me) is ostensibly only permitted in limited, controlled settings (usually to spy on a company’s employees).


 bad guys figure out how to neutralize