Flame, certificates, collisions. Oh my.

Update 6/6: Microsoft has given us more details on what’s going on here. If these collision attacks are truly novel, this tells us a lot about who worked on Flame and how important it is. 

Update 6/7: Yes, it’s officially a novel MD5 collision attack, with the implication that top cryptographers were involved in Flame’s creation. We truly are living in the future.

See detailed updates (and a timeline) at the bottom of this post.

If you pay attention to these things, you’ve heard that there’s a new piece of government-issued malware making the rounds. It’s called Flame (or sometimes Skywiper), and it’s basically the most sophisticated — or most bloated — piece of malicious software ever devised. Kaspersky gets the credit for identifying Flame, but the task of tearing it to pieces has fallen to a whole bunch of different people.

Normally I don’t get too excited about malware, cause, well, that kind of thing is somebody else’s problem. But Flame is special: if reports are correct, this is the first piece of malware ever to take advantage of an MD5 certificate collision to enable code signing. Actually, it may be the first real anything to use MD5 certificate collisions. Neat stuff.

What we know is pretty sketchy, and is based entirely on the information-sparse updates coming from Microsoft’s security team. Here’s the story so far:

Sometime yesterday (June 3), Microsoft released an urgent security advisory warning administrators to revoke two Intermediate certificates hanging off of the Microsoft root cert. These belong to the Terminal Services Licensing service. Note that while these are real certificates — with keys and everything — they actually have nothing to do with security: their sole purpose was to authorize, say, 20 seats on your Terminal Services machine.

Despite the fact that these certs don’t serve any real security purpose, and shouldn’t be confused with anything that matters, Microsoft hung them off of the same root as the real certificates it uses for, well, important stuff. Stuff like signing Windows Update packages. You see where this is going?

Actually, this shouldn’t have been a real problem, because these licensing certs (and any new certificates beneath them) should have been recognizably different from code-signing certificates. Unfortunately, someone in Product Licensing appears to have really screwed the pooch. These certificates were used to generate Licensing certificates for customers. And each of those certificates had the code signing bit set.

The result? Anyone who paid for a Terminal Services license could (apparently) sign code as if they were Microsoft. If you’re wondering what that looks like, it looks like this.

This is obviously a bad thing. For many reasons. Mikko Hypponen points out that many organizations whitelist software signing by Microsoft, so even if institutions were being paranoid, this malware basically had carte blanche.

Ok, so far this is really bad, but just a garden-variety screwup. I mean, a huge one, to be sure. But nothing really interesting.

Here’s where that changes. Just today, Microsoft released a new update. This is the new piece:

The Flame malware used a cryptographic collision attack in combination with the terminal server licensing service certificates to sign code as if it came from Microsoft. However, code-signing without performing a collision is also possible.

Now, I’m not sure why the ‘collision attack’ is necessary if code-signing is possible without a collision. But who cares! A collision attack! In the wild! On top-secret government-issued Malware! Dan Brown couldn’t hold a candle to this.

If we look at the Licensing certificates in question, we do indeed see that at least one — created in 2009 — uses the MD5 hash function, something everyone knows is a bad idea:

Certificate:    Data:        Version: 3 (0x2)        Serial Number:            3a:ab:11:de:e5:2f:1b:19:d0:56    Signature Algorithm: md5WithRSAEncryption        Issuer: OU=Copyright (c) 1997 Microsoft Corp., OU=Microsoft Corporation, CN=Microsoft Root Authority        Validity            Not Before: Dec 10 01:55:35 2009 GMT            Not After : Oct 23 08:00:00 2016 GMT        Subject: C=US, ST=Washington, L=Redmond, O=Microsoft Corporation, OU=Copyright (c) 1999 Microsoft Corp., CN=Microsoft Enforced Licensing Intermediate PCA        Subject Public Key Info:            Public Key Algorithm: rsaEncryption                Public-Key: (2048 bit)

And so… Well, I don’t really know. That’s where we run out of information. And end up with a lot of questions.

For one thing, why did the Flame authors need a collision? What extra capabilities did it get them? (Update: the best theory I’ve heard comes from Nate Lawson, who theorizes that the collision might have allowed the attackers to hide their identity. Update 6/6: The real reason has to do with certificate extensions and compatibility with more recent Windows versions. See the end of this post.)

More importantly, what kind of resources would it take to find the necessary MD5 collision? That would tell us a lot about the capabilities of the people government contractors who write malware like this. In 2008 it took one day on a supercomputer, i.e., several hundred PS3s linked together.

And just out of curiosity, what in the world was Microsoft doing issuing MD5-based certificates in 2009? I mean, the code signing bit is disastrous, but at least that’s a relatively subtle issue — I can understand how someone might have missed it. But making MD5 certificates one year after they were definitively shown to be insecure, that’s hard to excuse. Lastly, why do licensing certificates even need to involve a Certificate Signing Request at all, which is the vector you’d use for a collision attack?

I hope that we’ll learn the answers to these questions over the next couple of days. In the mean time, it’s a fascinating time to be in security. If not, unfortunately, a very good time for anyone else.

***

Update 6/5: For those who aren’t familiar with certificate collision attacks, I should clear up the basic premise. Most Certificate Authorities sign a Certificate Signing Request (CSR) issued by a possibly untrustworthy customer. The idea of an MD5 collision-finding attack is to come up with two different CSRs that hash to the same thing. One would be legitimate and might contain your Terminal Services licensing number. The other would contain… something else. By signing the first CSR, Microsoft would be implicitly creating a certificate on the second batch of information.

Finding collisions is a tricky process, since it requires you to muck with the bits of the public key embedded in the certificate (see this paper for more details). Also, some CAs embed a random serial number into the certificate, which really messes with the attack. Microsoft did not.

Finally, some have noticed that Microsoft is still using a root certificate based on MD5, one that doesn’t expire until 2020, and hasn’t been revoked. What makes this ok? The simple answer is that it’s not ok. However, Microsoft probably does not sign arbitrary CSRs with that root certificate, meaning that collision attacks are not viable against it. It’s only the Intermediate certs, the ones that actually sign untrusted CSRs you need to worry about — today.

***

Update 6/6: Microsoft has finally given us some red meat. Short summary: the Terminal Services Licensing certs do work to sign code on versions of Windows prior to Vista, with no collision attack needed. All in all, that’s a heck of a bad thing. But it seems that more recent versions of Windows objected to the particular X.509 extensions that were in the TS licensing certs. The government (or their contractors) therefore used a collision attack to make a certificate that did not have these extensions. From what I’m reading on mailing lists, the collision appears to be “new, and of scientific interest”.

If this pans out, it’s a big deal. Normally the government doesn’t blow a truly sophisticated cryptanalytic attack on some minor spying effort. Getting MD5 collisions up and running is a big effort; it’s not something you can do from a cookbook. But developing novel collision techniques is a step beyond that. I take this to mean that Flame’s authors were breaking out the big guns, which tells us something about its importance to our government. It also tells us that the creation of Flame may have involved some of the top mathematicians and cryptographers in (our?) intelligence services. This is an important datapoint.

***

Update 6/7: It looks like it does pan out. Marc Stevens — one of the authors of the earlier MD5 certificate collision papers — confirms that Flame’s certificate uses a novel collision-finding technique.

“Flame uses a completely new variant of a ‘chosen prefix collision attack’ to impersonate a legitimate security update from Microsoft. The design of this new variant required world-class cryptanalysis”

We can only speculate about why this would be necessary, but a good guess is that Flame is old (or, at very least, the crypto techniques are). If the collision technique was in the works prior to 2009 (and why wouldn’t it be?), Stevens et al. wouldn’t have had much relevance. For those who like details, a (very incomplete) timeline looks something like this:

  1. Mid-1990s: MD5 is effectively obsolete. Switch to a better hash function!
  2. August 2004: Wang and Yu present first (‘random’), manually-found collision on MD5.
  3. 2004-2007: Collisions extended to ‘meaningful’ documents. Lots of stuff omitted here.
  4. May 2007: (CWI) Stevens et al. publish a first impractical technique for colliding certificates.
  5. Late 2008: (CWI) Stevens et al. develop a practical certificate collision.
  6. December 2008: Vendors notified.
  7. Feburary 2009: Paper submitted to CRYPTO.
  8. Summer 2009: Source code released.

Even assuming that CWI team had perfect security with their result, conference program committees are hardly built for secrecy — at least, not from goverments. So it’s reasonable to assume that the Stevens et al. technique was known by February 2009, possibly earlier. Which means that the Flame developers may have had their own approach under development sometime before that date.

The really interesting question is: when did secret collision research get ahead of the public, academic stuff? Post-2007? Post-2004? Pre-2004? I doubt we’ll ever know the answer to this question. I sure would love to.

Update 6/12: Alex Sotirov has a great Summercon presentation with many of the details. The word from those who know is: don’t take his $20,000 figure too literally. We know nothing about the techniques used to find this collision.

Posts so far

The problem with blogs is that, well, they’re weblogs. The ‘good’ posts dribble off the bottom, where they get mixed in with the bad, and nobody ever sees them again. The more crap I write, the worse this problem is.

To fight this — and to prevent myself from writing the same post over and over again — I thought it might be helpful to compile a list of a few posts that aren’t too embarassing. If you’re new here, you can treat this as a table of contents to this blog.

(Hey, there are things going on in the world! The CRYPTO list of accepted papers has finally been published! There are neat attacks on cryptographic tokens! I want to write about all of it, but I just don’t have time today. So please accept these re-runs for now, and hopefully I’ll have new content soon.)

On the mess that is our public-key infrastructure:

  1. The Internet is broken, can we please fix it? On Trustwave & MITM attacks.
  2. TACK, a proposal for dynamically ‘pinning’ certificates.
High-level intro posts:
  1. It’s the end of the world as we know it, and I feel fine. Post-quantum crypto from 30,000 feet.
  2. What is the random oracle model and why should I care? An early series, a little embarrassing.
  3. Format preserving encryption. Or: how to encrypt a credit card number with AES.
  4. What’s TLS Snap Start? and So long False Start. On two (now withdrawn) TLS extensions.
  5. The future of electronic currency. On anonymous e-cash.
  6. Offline security through CAPTCHAs. A neat old idea for preventing dictionary attacks.
  7. Poker is hard, especially for cryptographers. All about mental poker.
  8. Fully-Homomorphic Encryption. Unfortunately this is still unfinished…
How to use cryptography (in)securely:
  1. How (not) to use symmetric encryption. A few of the worst pitfalls.
  2. What’s the deal with RC4? A history of attacks on an old stream cipher.
  3. How to choose an authenticated encryption mode. Very important!
  4. Random number generation, an illustrated primer. A look under the hood.
  5. Surviving a bad RNG. What to do if your (P)RNG isn’t carrying its weight.
  6. Circular security. A wonkier, more theoretical subject.
  7. On multiple encryption. Are you safer if you encrypt twice?
Crypto attack(s) of the week:
  1. On the BEAST attack. Note: written before the details were made public.
  2. XML Encryption. Why you should authenticate your ciphertexts.
  3. Side-channel attacks on DESFire. Neat.
  4. Datagram TLS. Alfardan & Paterson show that  timing attacks are (still) practical.
  5. 2011 Redux. A quick summary of a whole year.
  6. Satellite phone encryption is terrible. Attacks on two satphone ciphers.
  7. The story of EAX(prime). And why security proofs are like Knight Rider.
  8. A tale of two patches. Analyzing two recent OpenSSL bugs.
Rants:
  1. Digital Fortress: I read it so you don’t have to. Dan Brown embarrasses cryptography.
  2. Bram Cohen corrected. In which I randomly flame Bram Cohen.
  3. Bram Cohen corrects me? Bram turns out to be a good sport.
  4. Why Antisec matters. The security industry is a joke?
When I though this blog was a book:
  1. Introduction
  2. Where things fall apart: Primitives, Protocols

TACK

Those who read this blog know that I have a particular fascination with our CA system and how screwed up it is. The good news is that I’m not the only person who feels this way, and even better, there are a few people out there doing more than just talking about it.

Two of the ‘doers’ are Moxie Marlinspike and Trevor Perrin, who recently dropped TACK, a new proposal for ‘pinning’ TLS public keys. I would have written about TACK last week when it was fresh, but I was experimenting with a new approach to international travel where one doesn’t adjust oneself to the local timezone (nb: if you saw me and I was acting funny last week… sorry.)

TACK stands for Trust Assertions for Certificate Keys, but really, does it matter? TACK is one of those acronyms that’s much more descriptive in short form than long: it’s a way to ‘pin’ TLS servers to the correct public key even when a Certificate Authority is telling you differently, e.g., because the CA is misbehaving or has had its keys stolen.

In the rest of this post I’m going to give a quick overview of the problem that TACK tries to solve, and what TACK brings to the party.

Why do I need TACK?

For a long answer to this question you can see this previous post. But here’s the short version:

Because ‘secure communication’ on the Internet requires us to trust way too many people, many of of whom haven’t earned our trust, and probably couldn’t earn it if they tried.

Slightly less brief: most secure communication on the Internet is handled using the TLS protocol. TLS lets us communicate securely with anyone, even someone we’ve never met before.

While TLS is wonderful, it does have one limitation: it requires you to know the public key of the server you want to talk to. If an attacker can convince you to use the wrong public key (say, his key), you’ll end up talking securely to him instead. This is called a Man-in-the-Middle (MITM) attack and yes, it happens.

In principle we solve this problem using PKI. Any one of several hundred ‘trusted’ Certificate Authorities can digitally sign the server’s public key together with a domain name. The server sends the resulting certificate at the start of the protocol. If we trust all the CAs, life is good. But if any single one of those CAs lets us down, things get complicated.

And this is where the current CA model breaks down. Since every CA has the authority to sign any domain, a random CA in Malaysia can sign your US .com, even if you haven’t authorized it to, and even if that CA has never signed a .com before. It’s an invitation to abuse, since an attacker only need steal one CA private key anywhere in the world, and he can MITM any website.

The worst part of the ‘standard’ certificate model is how dumb it is. You’ve been connecting to your bank for a year, and each time it presented a particular public key certified by Verisign. Then one day that same site shows up with a brand new public key, signed by a CA from Guatemala. Should this raise flags? Probably. Will your browser warn you? Probably not. And this is where TACK comes in.

So what is TACK and how does it differ from other pinning schemes?

TACK is an extension to TLS that allows servers to ‘pin’ their public keys, essentially making the following statement to your TLS client:

This is a valid public key for this server. If you see anything else in this space, and I haven’t explicitly told you I’m changing keys, there’s something wrong.

Now, public-key pinning is not a new idea. A similar technique has been used by protocols like SSH for years, Google Chrome has a few static pins built in, and Google even has a draft HTTP extension that adds dynamic pinning capabilities to that protocol.

The problem with earlier pinning schemes is that they’re relatively inflexible. Big sites like Google and Facebook don’t run just one server, nor do they deploy a single public key. They run dozens or hundreds of servers, TLS terminators, etc., all configured with a mess of different keys and certificates. Moreover, configurations change frequently for business reasons. Pinning a particular public key to ‘facebook.com’ seems like a great idea, but probably isn’t as simple as you’d think it is. Moreover, a mistaken ‘pin’ is an invitation to a network disaster of epic proportions.

TACK takes an end-run around these problems, or rather, a couple of them:

  1. It adds a layer of indirection. Instead of pinning a particular TLS public key (either the server’s key, or some higher-level certificate public key), TACK pins sites to a totally separate ‘TACK key’ that’s not part of the certificates at all. You then use this key to make assertions about any of the keys on your system, even if each server uses a different one.
  2. It’s only temporary. A site pin lasts only a few days, no more than a month — unless you visit the site again to renew it. This puts pretty strict limits on the amount of damage you can do, e.g., by misconfiguring your pins, or by losing the TACK key.

So what exactly happens when I visit a TACK site?

So you’ve securely connected via TLS to https://facebook.com, which sports a valid certificate chain. Your browser also supports TACK. In addition to all the usual TLS negotiation junk, the server sends down a TACK public key in a new TLS extension field. It uses the corresponding TACK signing key to sign the server’s TLS public key. Next:

  1. Your browser makes note of the TACK key, but does nothing at all.
You see, it takes two separate connections to a website before any of the TACK machinery gets started. This is designed to insulate clients against the possibility that one connection might be an MITM.

The next time you connect, the server sends the same TACK public key/signature pair again, which activates the ‘pin’ — creating an association between ‘facebook.com’ and the TACK key, and telling your browser that this server public key is legitimate. If you last connected five days ago, then the ‘pin’ will be valid for five more days.

From here on out — until the TACK pin expires — your client will require that every TLS public key associated with facebook.com be signed by the TACK key. It doesn’t matter if Facebook has eight thousand different public keys, as long as each of those public keys gets shipped to the client along with a corresponding TACK signature. But if at any point your browser does not see a necessary signature, it will reject the connection as a possible MITM.

And that’s basically it.
The beauty of this approach is that the TACK key is entirely separate from the certificate keys. You can sign dozens of different server public keys with a single TACK key, and you can install new TLS certificates whenever you want. Clients’ browsers don’t care about this — the only data they need to store is that one TACK key and the association with facebook.com.

But what if I lose my TACK key or it gets stolen?

The nice thing about TACK is that it augments the existing CA infrastructure. Without a valid certificate chain (and a legitimate TLS connection), a TACK key is useless. Even if you lose the thing, it’s not a disaster, since pins expire relatively quickly. (Earlier proposals devote a lot of time to solving these problems, and even require you to back up your pinning keys.)

The best part is that the TACK signing key can remain offline. Unlike TLS private keys, the only thing the TACK key is used for is creating static signatures, which get stored on the various servers. This dramatically reduces the probability that the key will be stolen.

So is TACK the solution to everything?

TACK addresses a real problem with our existing TLS infrastructure, by allowing sites to (cleanly) set pins between server public keys and domain names. If widely deployed, this should help to protect us against the very real threat of MITM. It’s also potentially a great solution for those edge cases like MTA-to-MTA mailserver connections, where the PKI model actually doesn’t work very well, and pinning may be the most viable route to security.

But of course, TACK isn’t the answer to everything. The pins it sets are only temporary, and so a dedicated attacker with long-term access to a connection could probably manage to set incorrect pins. At the end of the day this seems pretty unlikely, but it’s certainly something to keep in mind.

If wishes were horses then beggars would ride… a Pwnie!

In case you’re wondering about the title above, I ripped it off from an old Belle Waring post on the subject of wishful thinking in politics. Her point (inspired by this Calvin & Hobbes strip) is that whenever you find yourself imagining how things should be in your preferred view of the world, there’s no reason to limit yourself. Just go for broke!

Take a non-political example. You want Facebook to offer free services, protect your privacy and shield you from targeted advertising? No problem! And while you’re wishing for those things, why not wish for a pony too!

This principle can also apply to engineering. As proof of this, I offer up a long conversation I just had with Dan Kaminsky on Twitter, related to the superiority of DNSSEC vs. application-layer solutions to securing email in transit. Short summary: Dan thinks DNSSEC will solve this problem, all we have to do is get it deployed everywhere in a reasonable amount of time. I agree with Dan. And while we’re daydreaming, ponies! (See how it works?)

The impetus for this discussion was a blog post by Tom Ritter, who points out that mail servers are horrendously insecure when it comes to shipping mail around the Internet. If you know your mailservers, there are basically two kinds of SMTP connection. MUA-to-MTA connections, where your mail client (say, Apple Mail) sends messages to an SMTP server such as GMail. And MTA-to-MTA connections, where Gmail sends the message on to a destination server (e.g., Hotmail).

Now, we’ve gotten pretty good at securing the client-to-server connections. In practice, this is usually done with TLS, using some standard server certificate that you can pick up from a reputable company like Trustwave. This works fine, since you know the location of your outgoing mail server and can request that the connection always use TLS.

Unfortunately, we truly suck at handling the next leg of the communication, where the email is shipped on to the next MTA, e.g., from Google to Hotmail. In many cases this connection isn’t encrypted at all, making it vulnerable to large-scale snooping. But even when it is secured, it’s not secured very well.

What Tom points out is that many mail servers (e.g., Gmail’s) don’t actually bother to use a valid TLS certificate on their MTA servers. Since this is the case, most email senders are configured to accept the bogus certs anyway, because everyone has basically given up on the system.

We could probably fix the certs, but you see, it doesn’t matter! That’s because finding that next MTA depends on a DNS lookup, and (standard) DNS is fundamentally insecure. A truly nasty MITM attacker can spoof the MX record returned, causing your server to believe that mail.evilempire.com is the appropriate server to receive Hotmail messages. And of course, mail.evilempire.com could have a perfectly legitimate certificate for its domain — which means you’d be hosed even if you checked it.

(It’s worth pointing out that the current X.509 certificate infrastructure does not have a universally-accepted field equivalent to “I am an authorized mailserver for Gmail”. It only covers hostnames.)

The question is, then, what to do about this?

There are at least three options. One is that we just suck it up and assume that email’s insecure anyway. If people want more security, they should end-to-end encrypt their mail with something like GPG. I’m totally sympathetic to this view, but I also recognize that almost nobody encrypts their email with GPG. Since we already support TLS on the MTA-to-MTA connection, perhaps we should be doing it securely?

The second view is that we fix this using some chimera of X.509 extensions and public-key pinning. In this proposal (inspired by an email from Adam Langley***), we’d slightly extend X.509 implementations to recognize an “I am a mailserver for Hotmail.com” field, we get CAs to sign these, and we install them on Hotmail’s servers. Of course, we’ll have to patch mailservers like Sendmail to actually check for these certs, and we’d have to be backwards compatible to servers that don’t support TLS at all — meaning we’d need to pin public keys to prevent downgrade attacks. It’s not a very elegant solution at all.

The third, ‘elegant’ view is that we handle all of our problems using DNSSEC. After all, this is what DNSSEC was built for! To send an email to Hotmail, my server just queries DNS for Hotmail.com, and (through the magic of public-key cryptography) it gets back a signed response guaranteeing that the MX record is legitimate. And a pony too!

But of course, back in the real world this is not at all what will happen, for one very simple reason:

  • Many mail services do not support DNSSEC for their mail servers.
  • Many operating systems do not support DNSSEC resolution. (e.g., Windows 8)

Ok, that’s two reasons, and I could probably add a few more. But at the end of the day DNSSEC is the pony with the long golden mane, the one your daughter wants you to buy her — right after you buy her the turtle and the fish and the little dog named Sparkles.

So maybe you think that I’m being totally unfair. If people truly want MTA-to-MTA connections to be secure, they’ll deploy DNSSEC and proper certificates. We’ll all modify Sendmail/Qmail/Etc. to validate that the DNS resolution is ‘secured’ and they’ll proceed appropriately. If DNS does not resolve securely, they’ll… they’ll…

Well, what will they do? It seems like there are only two answers to that question. Number one: when DNSSEC resolution fails (perhaps because it’s not supported by Hotmail), then the sender fails open. It accepts whatever insecure DNS response it can get, and we stick with the current broken approach. At least your email gets there.

Alternatively, we modify Sendmail to fail closed. When it fails to accomplish a secure DNS resolution, the email does not go out. This is the security-nerd approach.

Let me tell you something: Nobody likes the security-nerd approach.

As long as DNSSEC remains at pitiful levels of deployment, it’s not going to do much at all. Email providers probably won’t add DNSSEC support for MX records, since very few mailservers will be expecting it. Mailserver applications won’t employ (default, mandatory) DNSSEC checking because none of the providers will offer it! Around and around we’ll go.

But this isn’t just a case against DNSSEC, it relates to a larger security architecture question. Namely: when you’re designing a security system, beware of relying on things that are outside of your application boundary.

What I mean by this is that your application (or transport layer implementation, etc.) should not be dependent. If possible, it should try to achieve its security goals all by itself, with as few assumptions about the system that it’s running on, unless those assumptions are rock solid. If there’s any doubt that these assumptions will hold in practice, your system needs a credible fallback plan other than “ah, screw it” or “let’s be insecure”.

The dependence on a secure DNS infrastructure is one example of this boundary-breaking problem, but it’s not the only one.

For example, imagine that you’re writing an application depends on having a strong source of pseudo-random numbers. Of course you could get these from /dev/rand (or /dev/urand), but what if someone runs your application on a system that either (a) doesn’t have these, or (b) has them, but they’re terrible?

Now sometimes you make the choice to absorb a dependency, and you just move on. Maybe DNSSEC is a reasonable thing to rely on. But before you make that decision, you should also remember that it’s not just a question of your assumptions breaking down. There are human elements to think of.

Remember that you may understand your design, but if you’re going to be successful at all, someday you’ll have to turn it over to someone else. Possibly many someones. And those people need to understand the fullness of your design, meaning that if you made eight different assumptions, some of which occur outside of your control, then your new colleagues won’t just have eight different ways to screw things up. They’ll have 2^8 or n^8 different ways to screw it up.

You as the developer have a duty to yourself and to those future colleagues to keep your assumptions right there where you can keep an eye on them, unless you’re absolutely positively certain that you can rely on them holding in the future.

Anyway, that’s enough on this subject. There’s probably room on this blog for a longer and more detailed post about how DNSSEC works, and I’d like to write that post at some point. Dan obviously knows a lot more of the nitty-gritty than I do, and I’m (sort of) sympathetic to his position that DNSSEC is awesome. But that’s a post for the future. Not the DNSSEC-distant future, hopefully!

Notes:

* Dan informs me that he already has a Pwnie, hence the title.
** Thomas Ptacek also has a much more convincing (old) case against DNSSEC.
*** In fairness to Adam, I think his point was something like ‘this proposal is batsh*t insane’, maybe we should just stick with option (1). I may be wrong.

How to choose an Authenticated Encryption mode

If you’ve hung around this blog for a while, you probably know how much I like to complain. (Really, quite a lot.) You might even be familiar with one of my favorite complaints: dumb crypto standards. More specifically: dumb standards promulgated by smart people.

The people in question almost always have justifications for whatever earth-shakingly stupid decision they’re about to take. Usually it’s something like ‘doing it right would be hard‘, or ‘implementers wouldn’t be happy if we did it right‘. Sometimes it’s ‘well, we give the option to do it right‘. In the worst case they’ll tell you: ‘if it bothers you so much, why don’t you join the committee and suggest that idea yourself, Mr. Smartypants‘.

Well, first of all, it’s Dr. Smartypants. And moreover, I’ve tried. It doesn’t work.

Case in point: I happen to be lurking on the mailing list of a standards committee that recently decided to allow unauthenticated CBC mode encryption as an option in their new web encryption standard. When I pointed out that the exact same decision led to the failure of a previous standard — ironically, one that this new standard will probably replace — I was told, politely, that:

  1. Mandating authenticated encryption would be hard.
  2. Real implementers don’t know how to implement it.
  3. We already offer the option to use authenticated encryption.
  4. Stop telling us things we already know.

The worst part: they really did know. The committee included some smart, smart people. People who know that this is a bad idea, and who have decided either to just go with it, or else have convinced themselves that implementers won’t (a) pick the easy, insecure option, and then (b) screw it up completely. I have news for these people: Yes, they will. This is why we write standards.

After all this build-up, it may surprise you that this is not a post about standards committees. It’s not even a post about smart people screwing things up. What I’m here to talk about today is Authenticated Encryption, what the hell it is, why you need it. And finally, (assuming you’re good with all that) which of the many, many AE schemes should you consider for your application.
First, some background.

What’s Authenticated Encryption and why should I care?

For those of you who don’t know what AE is, I first need to explain one basic fact that isn’t well explained elsewhere:

Nearly all of the symmetric encryption modes you learned about in school, textbooks, and Wikipedia are (potentially) insecure.

This covers things like AES when used in standard modes of operation like CBC and CTR. It also applies to stream ciphers like RC4. Unfortunately, the list of potentially insecure primitives includes many of the common symmetric encryption schemes that we use in practice.

Now, I want to be clear. These schemes are not insecure because they leak plaintext information to someone who just intercepts a ciphertext. In fact, most modern schemes hold up amazingly well under that scenario, assuming you choose your keys properly and aren’t an idiot.

The problem occurs when you use encryption in online applications, where an an adversary can intercept, tamper with, and submit ciphertexts to the receiver. If the attacker can launch such attacks, many implementations can fail catastrophically, allowing the attacker to completely decrypt messages.

Sometimes these attacks requires the attacker to see only an error message from the receiver. In other cases all he needs to do is measure time it takes for the receiver to acknowledge the submission. This type of attack is known as a chosen ciphertext attack, and by far the most common embodiment is the ‘padding oracle attack‘ discovered in 2002 by Serge Vaudenay. But there are others.

The simplest way to protect yourself against these attacks is to simply MAC your ciphertexts with a secure Message Authentication Code such as HMAC-SHA. If you prefer this route, there are two essential rules:

  1.  Always compute the MACs on the ciphertext, never on the plaintext.
  2.  Use two different keys, one for encryption and one for the MAC.

Rule (1) prevents chosen-ciphertext attacks on block cipher modes such as CBC, since your decryption process can reject those attacker-tampered ciphertexts before they’re even decrypted. Rule (2) deals with the possibility that your MAC and cipher will interact in some unpleasant way. It can also help protect you against side-channel attacks.

This approach — encrypting something, then MACing it — is not only secure, it’s provably secure as long as your encryption scheme and MAC have certain properties. Properties that most common schemes do seem to possess.*

Dedicated AE(AD) modes

Unfortunately, the ‘generic composition’ approach above is not the right answer for everyone. For one thing, it can be a little bit complicated. Moreover, it requires you to implement two different primitives (say, a block cipher and a hash function for HMAC), which can be a hassle. Last, but not least, it isn’t necessarily the fastest way to get your messages encrypted.

The efficiency issue is particularly important if you’re either (a) working on a constrained device like an embedded system, or (b) you’re working on a fast device, but you just need to encrypt lots of data. This is the case for network encryptors, which have to process data at line speeds — typically many gigabytes per second!

For all of these reasons, we have specialized block cipher modes of operation called Authenticated Encryption (AE) modes, or sometimes Authenticated Encryption with Associated Data (AEAD). These modes handle both the encryption and the authentication in one go, usually with a single key.

AE(AD) modes were developed as a way to make the problem of authentication ‘easy’ for implementers. Moreover, some of these modes are lightning fast, or at least allow you to take advantage of parallelization to speed things up.

Unfortunately, adoption of AE modes has been a lot slower than one would have hoped for, for a variety of reasons. One of which is: it’s hard to find good implementations, and another is that there are tons and tons of AE(AD) schemes.

So, which AE mode should I choose?

And now we get down to brass tacks. There are a plethora of wonderful AE(AD) modes out there, but which one should you use? There are many things to consider. For example:

  • How fast is encryption and decryption?
  • How complicated is the implementation?
  • Are there free implementations out there?
  • Is it widely used?
  • Can I parallelize it?
  • Is it ‘on-line’, i.e., do I need to know the message length before I start encrypting?
  • Is it patented?
  • Does it allow me to include Associated Data (like a cleartext header)?
  • What does Matt Green think about it?

To answer these questions (and particularly the most important final one), let’s take a look at a few of the common AE modes that are out there. All of these modes support Associated Data, which means that you can pre-pend an unencrypted header to your encrypted message if you want. They all take a single key and some form of Initialization Vector (nonce). Beyond that, they’re quite different inside.

GCM. Galois Counter Mode has quietly become the most popular AE(AD) mode in the field today, despite the fact that everyone hates it. The popularity is due in part to the fact that GCM is extremely fast, but mostly it’s because the mode is patent-free. GCM is ‘on-line’ and can be parallelized, and (best): recent versions of OpenSSL and Crypto++ provide good implementations, mostly because it’s now supported as a TLS ciphersuite. As a side benefit, GCM will occasionally visit your house and fix broken appliances.

Given all these great features, you might ask: why does everyone hate GCM? In truth, the only people who hate GCM are those who’ve had to implement it. You see, GCM is CTR mode encryption with the addition of a Carter-Wegman MAC set in a Galois field. If you just went ‘sfjshhuh?’, you now understand what I’m talking about. Implementing GCM is a hassle in a way that most other AEADs are not. But if you have someone else’s implementation — say OpenSSL’s — it’s a perfectly lovely mode.

OCB. In performance terms Offset Codebook Mode blows the pants off of all the other modes I mention in this post. It’s ‘on-line’ and doesn’t require any real understanding of Galois fields to implement** — you can implement the whole thing with a block cipher, some bit manipulation and XOR. If OCB was your kid, he’d play three sports and be on his way to Harvard. You’d brag about him to all your friends.

Unfortunately OCB is not your kid. It belongs to Philip Rogaway, who also happens to hold a patent on it. This is no problem if you’re developing GPL software (it’s free for you), but if you want to use it in a commercial product — or even license under Apache — you’ll probably have to pay up. As a consequence OCB is used in approximately no industry standards, though you might find it in some commercial products.

EAX. Unlike the other modes in this section, EAX mode doesn’t even bother to stand for anything. We can guess that E is Encryption and A is Authentication, but X? I’m absolutely convinced that EAX is secure, but I cannot possibly get behind a mode of operation that doesn’t have a meaningful acronym.

EAX is a two-pass scheme, which means that encryption and authentication are done in separate operations. This makes it much slower than GCM or OCB, though (unlike CCM) it is ‘on-line’. Still, EAX has three things going for it: first, it’s patent-free. Second, it’s pretty easy to implement. Third, it uses only the Encipher direction of the block cipher, meaning that you could technically fit it into an implementation with a very constrained code size, if that sort of thing floats your boat. I’m sure there are EAX implementations out there; I just don’t know of any to recommend.

Whatever you do, be sure not to confuse EAX mode with its dull cousin EAX(prime), which ANSI developed only so it could later be embarrassingly broken.

CCM. Counter Mode with CBC MAC is the 1989 Volvo station wagon of AEAD modes. It’ll get you to your destination reliably, just not in a hurry. Like EAX, CCM is also a two-pass scheme. Unfortunately, CCM is not ‘on-line’, which means you have to know the size of your message before you start encrypting it. The redeeming feature of CCM is that it’s patent-free. In fact, it was developed and implemented in the 802.11i standard (instead of OCB) solely because of IP concerns. You can find an implementation in Crypto++.

The rest. There are a few more modes that almost nobody uses. These include XCBC, IAPM and CWC. I have no idea why the first two haven’t taken off, or if they’re even secure. CWC is basically a much slower version of GCM mode, so there’s no real reason to use it. And of course, there are probably plenty more that I haven’t listed. In general: you should use those at your own risk.

Summing up

So where are we?

In general, the decision of which cipher mode to use is not something most people make every day, but when you do make that decision, you need to make the right one. Having read back through the post, I’m pretty sure that the ‘right’ answer for most people is to use GCM mode and rely on a trusted free implementation, like the one you can get from OpenSSL.

But there are subcases. If you’re developing a commercial product, don’t care about cross-compatibility, and don’t mind paying ‘a small one-time fee‘, OCB is also a pretty good option. Remember: even cryptographers need to eat.

Finally, if you’re in the position of developing your own implementation from scratch (not recommended!) and you really don’t feel confident with the more complicated schemes, you should serious consider EAX or CCM. Alternatively, just use HMAC on your ciphertexts. All of these things are relatively simple to deal with, though they certainly don’t set the world on fire in terms of performance.

The one thing you should not do is say ‘gosh this is complicated, I’ll just use CBC mode and hope nobody attacks it’, at least not if you’re building something that will potentially (someday) be online and subject to active attacks like the ones I described above. There’s already enough stupid on the Internet, please don’t add more.

Notes:

* Specifically, your encryption scheme must be IND-CPA secure, which would apply to CBC, CTR, CFB and OFB modes implemented with a secure block cipher. Your MAC must be existentially unforgeable under chosen message attack (EU-CMA), a property that’s (believed) to be satisfied by most reasonable instantiations of HMAC.

** An earlier version of this post claimed that OCB didn’t use Galois field arithmetic. This commenter on Reddit correctly points out that I’m an idiot. It does indeed do so. I stand by my point that the implementation is dramatically simpler than GCM.

A tale of two patches

Nick Mathewson over at the Tor project points me to the latest vulnerability in OpenSSL’s implementation of TLS and DTLS (though only in some OpenSSL versions, YMMV). For those of you keeping score at home, this makes two serious flaws in the same small chunk of DTLS code in about four months.

I should note that Tor doesn’t use DTLS. In fact, based on a quick Google search, there may be more people with radioactive-spider-based superpowers than there are projects actually using OpenSSL DTLS (these folks being one possible exception). Moreover, it’s not clear that this bug (unlike the previous one) is useful for anything more than simple DoS.

But that doesn’t make it useless. Even if these things aren’t exploitable, bugs like this one provide us with the opportunity to learn something about how even ‘simple’ decryption code can go wrong. And that’s what we’re going to do in this post.

So let’s go take a look at the unpatched code in question.

This code handles the decryption of DTLS packets, and comes in a slightly older OpenSSL version, v1.0.0e (release 9/2011). To give you a flavor of how one could miss the first (less serious) issue, I was going to reproduce the entire 161-line megafunction in which the bug occurs. But it’s just too huge and awkward. Here’s the relevant bit:

int dtls1_enc(SSL *s, int send)
{
SSL3_RECORD *rec;
EVP_CIPHER_CTX *ds;
unsigned long l;
int bs,i,ii,j,k,n=0;
const EVP_CIPHER *enc; 
…
…        
if ((bs != 1) && !send)
  {
ii=i=rec->data[l-1]; /* padding_length */
i++;
if (s->options&SSL_OP_TLS_BLOCK_PADDING_BUG)
   {
/* First packet is even in size, so check */
if ((memcmp(s->s3->read_sequence,
                            “\0\0\0\0\0\0\0\0”,8) == 0) && !(ii & 1))
s->s3->flags|=TLS1_FLAGS_TLS_PADDING_BUG;
if (s->s3->flags & TLS1_FLAGS_TLS_PADDING_BUG)
i–;
   }
/* TLS 1.0 does not bound the number of padding bytes by the block size.
* All of them must have value ‘padding_length’. */
if (i > (int)rec->length)
   {
/* Incorrect padding. SSLerr() and ssl3_alert are done
* by caller: we don’t want to reveal whether this is
* a decryption error or a MAC verification failure
* (see http://www.openssl.org/~bodo/tls-cbc.txt) 
*/
return -1;
   }
for (j=(int)(l-i); j<(int)l; j++)
   {
if (rec->data[j] != ii)
      {
/* Incorrect padding */
return -1;
      }
   }
rec->length-=i;
            
rec->data += bs;    /* skip the implicit IV */
rec->input += bs;
rec->length -= bs;
   }
 }
return(1);
}

Now I could waste this whole post ranting about code quality, pointing out that variable names like ‘l’ and ‘bs’ were cute when Kernighan and his buddies were trying to get AWK small enough so they could write it down and type it in every day (or whatever they did for storage back then), but not so cute in 2012 inside of the most widely-used crypto library on earth.

I could also ask why this function is named “dtls1_enc” when in fact it actually contains decryption code as well as encryption code. I might even suggest that combining both operations into one massive, confusing function might have sounded like a better idea than it actually is.

But I’m not going to do all that, since that would be dull and the point of this post is to find a bug. So, do you see it? Hint: it’s in the boldfaced part.

Maybe I should give you a little more. Every DTLS packet begins with an ‘implicit’ Initialization Vector of length ‘bs’. The packet also comes with a bit of padding at the end, to bring the packet up to an even multiple of the cipher’s block size. Let ‘Mx’ represent message bytes and let ‘LL’ be the number of padding bytes expressed as a byte. Then the tail of the packet will look something like:

0x M1 M2 M3 M4 LL LL LL LL LL LL LL LL LL LL LL LL

An important note is that TLS 1.0 allows up to 255 padding bytes even if the blocksize is much less than that. So the last twenty-something lines of the boldfaced decryption code are basically checking the last byte of the decrypted message, then working backward through (possibly) multiple blocks of ‘bs’ bytes each, in order to strip off all of that ugly padding.

Do you see it now?

Ok, I’ll spoil it for you. The entirety of the bug comes in the statement “if (i > (int)rec->length)”, which ensures that the message is as long as the padding claims to be. What this doesn’t do is check that the Initialization Vector is there as well (update: I’ve edited this post a bit, since I got confused the first time!). Because of the missing check it’s possible to submit a short message that consists of only padding, in which case rec->length will be less than ‘bs’. At which point we flow through and hit this statement:

rec->length -= bs;

Oops. See what happens there? It might be helpful if I told you that rec->length is an unsigned long. So predictable consequences.

The OpenSSL folks describe this as a DoS vulnerability, not an exploitable one. I’m perfectly happy to take them at their word. But, yuck. This sort of stuff happens, I realize, but should it have to?

Since you’re still reading this, you’re obviously some kind of glutton for punishment. That probably means you’re going to stick around for the second (and somewhat older) issue, which was patched back in January. In fact, I wrote about it on this blog. To get there, you have to climb one level up to the caller of the function we just looked at.

This is easier said than done since — this being OpenSSL — of course the previous function isn’t called directly, it’s accessed via a function pointer! Oh lord. Ah, here we are:

static int
dtls1_process_record(SSL *s)
{
…
…
/* decrypt in place in ‘rr->input’ */
rr->data=rr->input;


enc_err = s->method->ssl3_enc->enc(s,0);  <<<<****** Call to the previous function!
if (enc_err <= 0)
 {
/* decryption failed, silently discard message */
if (enc_err < 0)
  {
rr->length = 0;
s->packet_length = 0;
  }
goto err;  <<<<****** Send an error message
}
…
…

/* check the MAC for rr->input (it’s in mac_size bytes at the tail) */
if (rr->length < mac_size)
  {
#if 0 /* OK only for stream ciphers */
al=SSL_AD_DECODE_ERROR;
SSLerr(SSL_F_DTLS1_PROCESS_RECORD,SSL_R_LENGTH_TOO_SHORT);
goto f_err;
#else
goto err;
#endif
  }
rr->length-=mac_size;
i=s->method->ssl3_enc->mac(s,md,0);
if (i data[rr->length]),mac_size) != 0)
  {
goto err;  <<<<****** Send an error message
  }
}
…
…
}
See it? Oh, maybe it will help if we revisit one of the bigger comments in the first function, the one that gets called:
 

/* Incorrect padding. SSLerr() and ssl3_alert are done
* by caller: we don’t want to reveal whether this is
* a decryption error or a MAC verification failure
* (see http://www.openssl.org/~bodo/tls-cbc.txt) 
*/
return -1;

Does that help? The people who wrote the first function knew full well how dangerous it is to reveal whether you’re failing due to a padding verification error or a MAC verification error. They even provided a link to the reason why!

Unfortunately the people writing the one-level up code didn’t understand the full implications of this, or didn’t realize that the information could leak out even if you don’t reveal exactly why you’ve barfed. People can learn why you failed even if there’s just a timing difference in when you give them the error code! This was known and mitigated in the TLS code, but not in the DTLS version.

And the end result is that there are two error conditions, occurring a significant distance from one another in the code. An attacker can monitor the decryption of chosen packets and use this information to slowly decrypt any plaintext. Ouch.

So what does it all mean?

You wanted meaning? I just wanted to look at some code.

But if I was to assign some arbitrary meaning to these mistakes, it’s that cryptographic code is frigging hard to write. And that more eyes does not necessarily mean fewer bugs, particularly if the code is messy and you have two versions doing substantially similar things (DTLS and TLS). It doesn’t help if your coding standard was basically invented on a dare.

OpenSSL has gotten to where it is today not for being a great library, but for basically being the library. And it’s certainly a good one, now that it’s been subjected to several years of unrelenting scrutiny. But the DTLS code is new and hasn’t received that same level of attention, which is why it’s fun to watch the bugs get shaken out all over again (unfortunately the first bug also appears in TLS code, which is harder to explain). I’m sure we haven’t seen the last of it.

The future of electronic currency

Crypto is fantastic for many things, but those who readthis blog know that I have a particular fascination for its privacy applications. Specifically, what interests me are the ways we can use cryptography to transact (securely) online, without revealing what we’re doing, or who we’re doing it with.

This is particularly relevant, since today we’re in the middle of an unprecedented social and technological experiment: moving our entire economy out of metal and paper and into the ‘net. I’ve already had to explain to my four-year old what newspapers are; I imagine he’ll have a similarly experience when his children ask why people once carried funny pieces of paper around in their wallet.

Between credit and debit cards, EFT, online banking and NFC, it seems like the days of cash are numbered. Unfortunately, all is not sunshine and roses. The combination of easy-to-search electronic records and big data seems like a death-knell for our individual privacy. Cryptography holds the promise to get some of that privacy back, if we want it.

In this post I’m going to take a very quick look at a few privacy-preserving ‘e-cash’ technologies that might help us do just that. (And yes, I’ll also talk about Bitcoin.)

Why don’t we have electronic cash today?

The simple answer is that we already have electronic money; we just don’t call it that. Right now in its mainstream incarnation, it takes the form of little plastic cards that we carry around in our wallets. If you live in a developed nation and aren’t too particular about tipping valets, you can pretty much survive without ever touching hard currency.

The problem is that credit and debit cards are not cash. They’re very good for money transfers, but they have two specific limitations: first, they require you to access an online payment network. This means that they lose their usefulness at exactly the moment when you need them most: typically, after a disaster has wiped out or severely limited your connectivity (e.g., most hurricanes in Florida, NYC the morning after 9/11, etc).

Secondly, funds transfer systems offer none of the privacy advantages of real cash. This is probably by (government) preference: untraceable cash lends itself to unsavory activities, stuff like drug dealing, arms purchases and tax evasion. Our modern banking system doesn’t necessarily stop these activities, but it’s a godsend for law enforcement: just about every transaction can be traced down to the $0.01. (And even if you aren’t a drug dealer, there are still plenty of folks who’ll pay good money for a copy of your spending history, just so they can sell you stuff.)

The genesis of private e-cash

chaum_1
David Chaum

Credit for the invention of true, privacy-preserving electronic cash generally goes to David Chaum. Chaum proposed his ideas in a series of papers throughout the 1980s, then made a fortune providing the world with untraceable electronic cash.

Well, actually, the statement above is not quite accurate. According to legend, Chaum turned down lucrative offers from major credit card companies in favor of starting his own e-cash venture. I don’t need to tell you how the story ends — you’ve probably already noticed that your wallet isn’t full of untraceable electronic dollars (and if it is: I’m sorry.)

There’s an important lesson here, which is that getting people to adopt electronic cash requires a lot more than just technology. Fortunately, the failure of e-cash has a silver lining, at least for the field of cryptography: Chaum went on to pioneer anonymous electronic voting and a whole mess of other useful stuff.

Like many e-cash systems since, Chaum’s earliest paper on the e-cash proposed to use digital ‘coins’, each of some fixed denomination (say, $1). A coin was simply a unique serial number, generated by the holder and digitally signed using a private key known only to the bank. When a user ‘spends’ a coin, the merchant can verify the signature and ‘deposit’ the coin with the bank — which will reject any coin that’s already been spent.

(Of course, this doesn’t prevent the merchant from re-spending your hard earned money. To deal with this, the user can replace that serial number with a freshly-generated public key for a signature scheme. The bank will sign the public key, then the user can provide the merchant with the public key — signed by the bank — and use the corresponding signing key to sign the merchant’s name and transaction info.)

However you do it, the system as described has a crucial missing element: it’s not private. The bank knows which serial numbers it signs for you, and also knows where they’re being spent. This provides a linkage between you and, say, that anarchist bookstore where you’re blowing your cash.

To address this, Chaum replaced the signing process with a novel blind signature protocol. Blind signature is exactly what it sounds like: a way for the bank to sign a message without actually seeing it. Using this technology, the user could make up a serial number and not tell the bank; the blind signature protocol would provide the necessary signature. Even if the bank was trying to track the coins, it wouldn’t be able to link them to the user.

Chaum even provided a nice real-world analogy for his idea: place a document inside of an element along with a sheet of carbon paper, then let the bank sign the outside of the envelope, conveying the signature through and onto the document. This doesn’t literally describe how blind signatures work, but the real cryptographic constructions aren’t that much worse: you can readily obtain blind versions of RSA, DSA and the Schnorr/Elgamal signatures without (mostly) breaking a sweat (see this footnote for details).

The double-spending problem and going offline

Digital signatures do one thing very well: they prevent unauthorized users from issuing their own coins. Unfortunately they don’t prevent a second serious problem: users who copy legitimate coins.

Copying is where electronic cash really differs from its physical equivalent. Real money is hard to copy — by design. If it wasn’t, we wouldn’t use it. When people get too clever at copying it, we even send men with guns to shut them down.

Electronic coins are very different. It’s almost impossible to work with data without copying it; from long-term storage to RAM, from RAM to the processor cache, from one computer to another over a network. Electronic coins must be copied, and this fundamentally changes the nature of the problem. The boogeyman here is ‘double spending‘, where a user tries to spend the same valid coin with many different merchants. Left unchecked, double-sending does more than screw over a merchant. It can totally debase the currency supply, making coins almost impossible for merchants to trust.

Chaum’s original solution dealt with double-spenders by requiring the bank to be online, so users could immediately deposit their coins — and make sure they were fresh. This works great, but it’s damn hard to handle in a system that works offline, i.e., without a live network connection. Indeed, offline spending is the big problem that most e-cash solutions have tried to tackle.

There are two basic solutions to the offline problem. Neither is perfect. They are:

  • Use trusted hardware. Force users to store their coins inside of some piece of bank-trusted (and tamper-resistant) piece of hardware such as a cryptographic smartcard. The hardware can enforce correct behavior, and prevent users from learning the actual coin values.
  • Revoke double-spenders’ anonymity. Alternatively, it’s possible to build e-cash systems that retain the users’ anonymity when they participate honestly, but immediately revokes their anonymity when they cheat (i.e., double-spend the same coin).

Although these solutions are elegant, they also kind of suck. This is because neither is really sufficient to deal with the magnitude of the double-spending problem.

To understand what I’m talking about, consider the following scam: I withdraw $10,000 from the bank, then spend each of my coins with 1,000 different offline merchants. At the end of the day, I’ve potentially walked away with $10,000,000 in merchandise (assuming it’s portable) before anyone realizes what I’ve done. That’s a lot of dough for a single scam.

In fact, it’s enough dough that it would justify some serious investment in hardware reverse-engineering, which makes it hard to find cost-effective hardware that’s sufficient to handle the threat. Finding the owner of the coin isn’t much of a deterrent either — most likely you’ll just find some guy in Illinois who had his wallet stolen.

That doesn’t mean these approaches are useless: in fact, they’re very useful in certain circumstances, particularly if used in combination with an online bank. Moreover the problem of revealing a user’s identity (on double-spend) is an interesting one. There are several schemes that do this, including one by Chaum, Fiat and Naor, and a later (very elegant) scheme by Stefan Brands. (For a bit more about these schemes, see this footnote.)

Compact wallets and beyond

There have been quite a few developments over the past few years, but none are as dramatic as the original schemes. Still, they’re pretty cool.

One scheme that deserves a few words is the ‘Compact e-Cash‘ system of Camenisch, Hohenberger and Lysyanskaya. This system is nice because users can store millions of e-coins in a relatively small format, but also because it uses lots of neat crypto — including signatures with efficient protocols and zero-knowledge proofs.

At a very high level, when a user withdraws n coins from the bank in this system, the bank provides the user with a digital signature on the following values: the user’s public key, the number of coins n withdrawn, and a secret seed value seed that’s generated cooperatively by the bank and the user.

The bank learns the number of coins and user’s public key, but only the user learns seed. To spend the ith coin in the wallet, the user generates a ‘serial number’ SN = F(seed, i), where F is some pseudo-random function. The user also provides a non-interactive zero-knowledge proof that (a) 0 < i < n, (b) SN is correctly formed, and (c) she has a signature on seed from the bank (among other things). This zero-knowledge proof is a beautiful thing, because it does not leak any information beyond these statements, and can’t even be linked back to the user’s key in the event that she loses it. The online bank records each serial number it sees, ensuring that no coin will ever be spent twice.

This may seem pretty complicated, but the basic lesson is that we can do lots of neat things with these technologies. We can even build coins that can be spent k times for some arbitrary k, only revealing your identity if they’re used more times than that; this turns out to be useful anonymous login applications, where users want to access a resource a fixed number of times, but don’t want anyone counting their accesses.

Unfortunately, we haven’t managed to build any of this stuff and deploy it in a practical setting.

Bitcoin

Which brings us to the one widely-deployed, practical electronic cash system in the world today. What about Bitcoin?

I’m a big fan of Bitcoin (from a technical perspective), but it has a few limitations that make Bitcoins a little bit less private than real e-cash should be.

Despite the name, Bitcoin doesn’t really deal with ‘coins’: it’s actually a transaction network. Users generate blocks of a certain value then transfer quantities of currency using ECDSA public keys as identifiers. The core innovation in Bitcoin is a distributed public bulletin-board (the ‘block-chain’) that records every transaction in Bitcoin’s history. This history lets you check that any given chunk of currency has a valid pedigree.

While the Bitcoin block-chain is essential to security, it’s also Bitcoin’s privacy achilles heel. Since every transaction is public — and widely disseminated — there’s no hiding that it took place. To make up for this, Bitcoin offers pseudonymity: your public key isn’t tied to your identity in any way, and indeed, you can make as many of them as you want. You can even transfer your coins from one key to another.

Now, I’m not really complaining about this. But it should be noted that pseudonymity is to anonymity what sugar-free chocolates are to the real thing. While I don’t know of anyone who’s actively looking to de-anonymize Bitcoin transactions (scratch that, Zooko points out that some people are), there has been plenty of work on extracting (or ‘re-identifying’) pseudonymized data sets. If you don’t believe me, see this work by Narayanan and Shamtikov on de-anonymizing social network data, or this one that does the same thing for the Netflix prize dataset. And those are just two of many examples.

Many knowledgable Bitcoin users know this, and some have even developed Bitcoin ‘mixers’ that stir up large pools of Bitcoin from different users, in the hopes that this will obfuscate the transaction history. This sounds promising, but has a lot of problems — starting with the fact that none few seem to be actually online as I write this post.* Even if one was available, you’d basically be placing your privacy trust into the hands of one party who could totally screw you. (A large, distributed system like Tor could do the job, but none seems to be on the horizon). Finally, you’d need a lot of transaction volume to stay safe.

At the same time, it seems difficult to shoehorn the e-cash techniques from the previous sections into Bitcoin, because those systems rely on a centralized bank, and also assume that coins are used only once. Bitcoin has no center, and coins are used over and over again forever as they move from user to user. Any anonymous coin solution would have to break this linkage, which seems fundamentally at odds with the Bitcoin design. (Of course that doesn’t mean it isn’t possible! ;)**

In summary

This has hardly been an exhaustive summary of how e-cash works, but hopefully it gives you a flavor of the problem, along with a few pointers for further reading.

I should say that I don’t live the most interesting life, and about the only embarrassing thing you’ll see on my credit cards is the amount of money we waste on Diet Coke (which is totally sick). Still, this isn’t about me. As our society moves away from dirty, messy cash and into clean — and traceable — electronic transactions, I really do worry that we’re losing something important. Something fundamental.

This isn’t about avoiding marketers, or making it easier for people to have affairs. Privacy is something humans value instinctively even when we don’t have that much to hide. It’s the reason we have curtains on our windows. We may let go of our privacy today when we don’t realize what we’re losing, but at some point we will realize the costs of this convenience. The only question is when that will be, and what we’ll do about it when the day comes.

Notes:

* I was wrong about this: a commenter points out that Bitcoin Fog is up and running as a Tor hidden service. I’ve never tried this, so I don’t know how well it works. My conclusion still stands: mixing works well if you trust the BF operators and there’s enough transaction volume to truly mix your spending. We shouldn’t have to trust anyone.

** Some people have tried though: for example, OpenCoin tries to add Chaum-style cash to Bitcoin. Ditto Open Transactions. From what I can tell, these protocols still do Chaumian cash ‘old style’: that is, they require a trusted ‘bank’, or ‘issuer’ and don’t actually integrate into the distributed trust framework of Bitcoin. Still very nice work. h/t commenters and Stephen Gornick (who also fixed a few typos).

An update on the TLS MITM situation

A couple months back I wrote a pretty overwrought post lamenting the broken state of our PKI. At the time, I was kind of upset that ‘trusted’ Certificate Authorities (*ahem*, Trustwave) had apparently made a business of selling that trust for the purpose of intercepting SSL/TLS connections.

Now, I may be off base, but this seems like a bad thing to me. It also seemed like pretty stupid business. After all, it’s not like certificates are hard to make (seriously — I made three while writing the previous sentence). When your sole distinguishing feature is that people trust you, why would you ever mess with that trust?

In any case, the worst part of the whole thing was a suspicion that the practice didn’t end with Trustwave; rather, that Trustwave was simply the CA that got caught. (No, this doesn’t make it better. Don’t even try that.)

But if that was the case, then who else was selling these man-in-the-middle ‘skeleton’ certificates? Who wasn’t? Could I just call up and order one today, or would it be all dark parking lots and windowless vans, like the last time I bought an 0day from VUPEN? (Kidding. Sort of.)

The saddest part of the whole story is that out of all the major browser vendors, only one — the Mozilla foundation, makers of Firefox — was willing to take public action on the issue. This came in the form of a letter that Mozilla sent to each of the major CAs in the Mozilla root program:

Please reply by March 2, 2012, to confirm completion of the following actions or state when these actions will be completed.

1) Subordinate CAs chaining to CAs in Mozilla’s root program cannot be used for MITM or “traffic management” of domain names or IPs that the certificate holder does not legitimately own or control, regardless of whether it is in a closed and controlled environment or not. Please review all of the subordinate CAs that chain up to your root certificates in NSS to make sure that they cannot be used in this way. Any existing subordinate CAs that can be used for that purpose must be revoked and any corresponding HSMs destroyed as soon as possible, but no later than April 27, 2012.

Which brings me to the point of this post. March 2 passed a long time ago. The results are mostly in. So what have we learned?


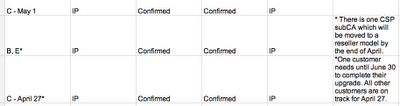
(Note: to read the linked spreadsheet, look at the column labeled “Action #1”. If it contains an A, B, or E, that means the CA has claimed innocence — it does not make SubCAs for signing MITM certificates, or else it does make SubCAs, but the holders are contractually-bound not to abuse them.* If there’s a C or a D there, it means that the CA is working the problem and will have things sorted out soon.)

The high-level overview is that most of the Certificate Authorities claim innocence. They simply don’t make SubCAs (now, anyway). If they do, they contractually require the holders not to use them for MITM eavesdropping. One hopes these contracts are enforceable. But on the surface, at least, things look ok.

There are a couple of exceptions: notably Verizon Business (in my hometown!), KEYNECTIS and GlobalSign. All three claim to have reasonable explanations, and are basically just requesting extensions so they can get their ducks in a row (KEYNECTIS is doing in-person inspections to make sure nothing funny is going on, which hopefully just means they’re super-diligent, and not that they’re picking up MITM boxes and throwing them in the trash.) **

But the upshot is that if we can believe this self-reported data, then Trustwave really was the outlier. They were the only people dumb enough to get into the business of selling SubCAs to their client for the purpose of intercepting TLS connections. Or at very least, the other players in this business knew it was a trap, and get themselves out long ago.

Anyone else believe this? I’d sure like to.

Notes:

* ‘Abuse’ here means signing certificates for domains that you don’t control. Yes, it’s unclear how strong these contracts are, and if there’s no possibility for abuse down the line. But we can only be so paranoid.

** I confess there some other aspects I don’t quite follow here — for example, why are some ‘compliant’ CAs marked with ‘CP/CPS does not allow MITM usage’, while others are ‘In Progress’ in making that change. I’m sure there’s a good technical reason for this. Hopefully the end result is compliance all around.

Wonk post: Circular security

Apologies in advance for a super-wonky post, but I’m in kind of a wonky mood this week. It happens that I’m putting together a talk on the subject of circular security, and I figured this blog might be a good place to get my thoughts together.

If you’ve never heard of circular security, don’t feel bad — you’re in good company. In a nutshell, circular security describes the way that an encryption scheme behaves when you ask it to encrypt its own key. In theory, that behavior can be pretty unpredictable.

The key word in the previous sentence is ‘theory’. Circular security is a very interesting research area, but if your primary reason for reading this blog is to learn about practical things, this post may not be for you. (Though please come back next week, when I hope to be writing about electronic cash!)

Assuming you’re still reading, the first order of business is to talk about what circular security (or insecurity) is in the first place. To do that, we need to define what it means for an encryption scheme to be ‘secure’. And that means a discussion of semantic security.

Semantic Security

Semantic security is one of the earliest and most important security definitions in our field. It’s generally considered to be the minimum bar for any modern ‘secure’ encryption scheme. In English, the informal definition of semantic security is something like this:

An attacker who sees the encryption of a message — drawn from a known, or even chosen message space — gains approximately the same amount of information as they would have obtained if they didn’t see the encryption in the first place. (The one exception being the length of the message.)

This is a nice, intuitive definition since it captures what we really want from encryption.

You see, in an ideal world, we wouldn’t need encryption at all. We would send all of our data via some sort of magical, buried cable that our adversary couldn’t tap. Unfortunately, in the real world we don’t have magical cables: we send our data via the public WiFi at our neighborhood Starbucks.

Semantic security tells us not to worry. As long as we encrypt with a semantically-secure scheme, the adversary who intercepts our encrypted data won’t learn much more than the guy who didn’t intercept it at all — at worst, he’ll learn only the amount of data we sent. Voila, security achieved.

(Now, just for completeness: semantic security is not the strongest definition we use for security, since it does not envision active attacks, where the adversary can obtain the decryption of chosen ciphertexts. But that’s a point for another time.)

Unfortunately, before we can do anything with semantic security, we need to turn the English-language intuition above into something formal and mathematical. This is surprisingly complicated, since it requires us to formalize the notion of ‘an attacker gains approximately the same amount of information‘. In the early definitions this was done by making grand statements about predicate functions. This approach is faithful and accurate. It’s also kind of hard to do anything with.

Fortunately there’s a much simpler, yet equivalent way to define semantic security. This definition is called ‘indistinguishability under chosen plaintext attack‘, or IND-CPA for short. IND-CPA is described by the following game which is ‘played’ between an adversary and some honest party that we’ll call the challenger:

  1. The challenger generates a public/private keypair, and gives the public key to the adversary.
  2. The adversary eventually picks two equal-length messages (M0, M1) from the set of allowed plaintexts, and sends them to the challenger.
  3. The challenger flips a coin, then returns the encryption of one of the messages under the public key.
  4. The attacker tries to guess which message was encrypted. He ‘wins’ if he guesses correctly.

(This game can also be applied to symmetric encryption. Since there’s no public key in a symmetric scheme, the challenger makes up the lost functionality by providing an encryption oracle: i.e., it encrypts messages for the adversary as she asks for them.)

A quick glance at the game should convince you that even a moron adversary can win this game. In fact, if the adversary simply guesses randomly he’ll be right exactly half the time. Hence the real question is: how much better can he do?

And that leads us to our (basically) formal definition:

A scheme is IND-CPA secure if no adversary can win the above game with probability (significantly) greater than 1/2.

The term ‘significantly’ in this case hides a lot of detail — typically it means that ‘non-negligibly‘. In many schemes we also require the adversary to run in limited time (i.e., be a probabilistic polynomial-time Turing machine). But details, details…

Encrypting your own key

One of the weirder aspects of the IND-CPA definition above is that it doesn’t handle a very basic (and surprisingly common!) use case: namely, cases where you encrypt your own secret key.

Believe it or not, this actually happens. If you use a disk encryption system like Bitlocker, you maybe already be encrypting your own keys, without even noticing it. Moreover, newer schemes like Gentry’s Fully Homomorphic Encryption depend fundamentally on this kind of “circular” encryption.

It seems surprising that IND-CPA can give us such a strong notion of security — where the attacker learns nothing about a plaintext — and yet can’t handle this very simple case. After all, isn’t your secret key just another message? What makes it special?

The technical answer to this question hangs on the fact that the IND-CPA game above only works  with messages chosen by the adversary. Specifically, the adversary is asked to attack the encryption of either M0 or M1, which he chooses in step (2). Since presumably — if the scheme is secure — the adversary doesn’t know the scheme’s secret key, he won’t be able to submit (M0,M1) such that either message contains the scheme’s secret key. (Unless he makes a lucky guess, but this should happen with at most negligible probability.)

What this means is that an encryption scheme could do something terribly insecure when asked to encrypt its own secret key. For example, it could burp out the secret key without encrypting it at all! And yet it would still satisfy the IND-CPA definition. Yikes! And once you raise the possibility that such a scheme could exist, cryptographers will immediately wants to actually build it.

(This may seem a little perverse: after all, aren’t there enough broken schemes in the world without deliberately building more? But when you think about it, this kind of ‘counterexample’ is extremely valuable to us. If we know that such oddball, insecure schemes can exist, that motivates to watch out for them in the real constructions that we use. And it tells us a little about the strength of our definitions.)

It turns out that there’s a ‘folklore’ approach that turns any IND-CPA secure public-key encryption scheme into one that’s still IND-CPA secure, but is also totally insecure if it ever should encrypt its own secret key.

The basic approach is to modify the original scheme by changing the encryption algorithm as follows:

  1. On input a public key and a message to be encrypted, it tests to see if the message is equal to the scheme’s secret key.*
  2. If not, it encrypts the message using the original scheme’s encryption algorithm (which, as we noted previously, is IND-CPA secure).
  3. If the message is equal to the secret key, it just outputs the secret key in cleartext.
It’s pretty easy to see that this scheme is as secure as the original scheme for messages that aren’t the secret key. It’s also easy to see that it’s totally insecure when you do encrypt the actual secret key. (Though I’ve glossed over a small technical challenge in step 2, see footnote*).

Circles and cycles

Just as cryptographers were congratulating each other for answering the previous question — showing that there are schemes that fail catastrophically when they encrypt their own secret key — some smartass decided to up the stakes.

The question (s)he asked was: what if two people encrypt each other’s secret keys?

Let’s be clear what I’m saying here. Imagine that Alice decides to entrust Bob with her secret key, so she wraps it up under his public key (say, sending him a PGP encrypted email). And imagine that Bob decides to do exactly the same with his key, encrypting it under Alice’s public key. We now have the following ‘key cycle’:

CA = Encrypt(pkA, skB),               CB = Encrypt(pkB, skA)

To be clear, IND-CPA by itself tells us that it’s perfectly secure for Alice to encrypt her own key under Bob’s key (or vice versa). There’s no problem there. However, the minute Bob also encrypts Alice’s secret key, a cycle is formed — and semantic security doesn’t tell us anything about whether this is secure.

So this is worrisome in theory, but are there actual schemes where such cycles can cause problem?

Up until 2010, the answer was: no. It turns out to be much harder to find a counterexample for this case, since the approach described in the previous section doesn’t work. You can’t just hack a little bit of code into the encryption algorithm; the ciphertexts are encrypted independently. At the time they’re encrypted, the ciphertexts are perfectly secure. They only become insecure when they come into close proximity with one another.

(If a weird analogy helps, think of those encrypted keys like two hunks of Plutonium, each inside of its own briefcase. As long as they’re apart, everything’s fine. But get them close enough to one another, they interact with one another and basically ruin your whole day.)

It gets worse

A breakthrough occurred at Eurocrypt 2010, where Acar, Belenkiy, Bellare and Cash showed that indeed, there is a scheme that’s perfectly IND-CPA secure in normal usage, but fails when Alice and Bob encrypt their keys in a cycle like the one described above.

The Acar et al. scheme is based on certain type of elliptic-curve setting known as bilinear SXDH, and what they show is that when Alice and Bob create a key cycle like the one above, an adversary can recognize it as such.

To be clear, what this means is that the ciphertexts (Encrypt(pkA, skB), Encrypt(pkB, skA)) jointly leak a little bit of information — simply the fact that they encrypt each other’s secret keys! This may not seem like much, but it’s far more than they should ever reveal.

The Acar et al. result is interesting to me, because along with my colleague Susan Hohenberger, I was thinking about the same problem around the same time. We independently came up with a similar finding just a few months after Acar et al. submitted theirs — crappy luck, but it happens. On the bright side, we discovered something slightly worse.

Specifically, we were able to construct a scheme that’s totally secure in normal usage, but becomes catastrophically insecure the minute Alice and Bob encrypt each others’ secret keys. This means in practice that if two parties innocently encrypt a key cycle, then both of their secret keys become public. This means every message that either party has ever encrypted (or will encrypt) becomes readable. Not good!**

The worst part is that both the Acar et al. scheme and our scheme are (almost) normal-looking constructions. They could be real schemes that someone came up with and deployed in the real world! And if they did, and if someone encrypted their secret keys in a cycle, things would be very bad for everyone.

So what do we do about this?

The solution to this problem is to develop schemes that can handle (by design) the case where someone encrypts a secret key, or a function of a secret key. This concept is known as Key-Dependent Message (KDM) security, and it’s been the subject of some research.

Unfortunately, building provably KDM-secure schemes is not an easy task, at least, not without resorting to artificial constructs like random oracles. While this may change in the future, for the moment we have a ways to go before we can build truly efficient schemes that don’t (potentially) have problems like the above.

And this is what makes cryptography so interesting. No matter what we say about our schemes being  ‘provably secure’, the truth is: there’s always something we haven’t thought of. Just when you thought you’d finally solved all the major security problems (ha!), another one will always pop up to surprise you.

Notes:

* The obvious objection is that a public key encryption algorithm takes in only a public key and a message. It doesn’t take in the scheme’s secret key. So: how can it check whether the given message is the encryption of the secret key? There’s a general solution to this, but I’ll leave it as an exercise for the reader.

** David Cash, Susan Hohenberger and I have summarized these results, along with several related to symmetric encryption, and will be presenting them at PKC 2012. If you’re interested, a full version of our paper should appear here shortly.

So long False Start, we hardly knew ye

Last week brought the sad news that Google is removing support for TLS False Start from the next version of Chrome. This follows on Google’s decision to withdraw TLS Snap Start, and caps off the long line of failures that started with the demise of Google Wave. Industry analysts are already debating the implications for Larry Page’s leadership and Google’s ‘Social’ strategy.

(I am, of course, being facetious.)

More seriously, it’s sad to see False Start go, since the engineering that led to False Start is one of the most innovative things happening in Internet security today. It’s also something that only Google can really do, since they make a browser and run a very popular service. The combination means they can try out new ideas on a broad scale without waiting for IETF approval and buy-in. Nor are they shy about doing this: when the Google team spots a problem, they tackle it head-on, in what I call the ‘nuke it from orbit’ approach. It’s kind of refreshing.

Of course, the flipside of experimentation is failure, and Google has seen its share of failed experiments. The last was Snap Start, which basically tackled the same problem as False Start, but in a different way. And now False Start is going the way of the coelacanth: it’ll still exist, but you’ll have a hard time finding it.

The response from the security community has been a lot of meaningful chin-tapping and moustache-stroking, but not (surprisingly) a lot of strong opinions. This is because — as we all recently discovered — none of us had really spent much time thinking about False Start before Google killed it.* And so now we’re all doing it retroactively.

What the heck is (was) False Start anyway?

Secure web (TLS) is dirt slow. At least, that’s the refrain you’ll hear from web companies that don’t deploy it. There are many objections but they usually boil down to two points: (1) TLS requires extra computing hardware on the server side, and (2) it adds latency to the user experience.

Why latency? Well, to answer that you only need to look at the TLS handshake. The handshake establishes a communication key between the server and client. It only needs to happen once per browsing session. Unfortunately it happens at the worst possible time: the first time you visit a new site. You never get a second chance to make a first impression.

Why is the standard handshake so slow? Short answer: key establishment requires two round trips — four ‘flights’ — before the client can send any actual data (say, an HTTP GET request). If you’re communicating via undersea cable, or if you’re using a mobile phone with a huge ping time (my AT&T phone just registered 250ms!) this is going to add up.

sy10660a
Standard TLS handshake (source). Application data exchange only occurs at step (9) in the diagram. Note that step (5) is optional, and steps (4),(7) can be conducted in the same message ‘flight’.

This is the problem that False Start tried to address. The designers — Langley, Modadugu and Moeller — approached this in the simplest possible way: they simply started sending data earlier.

You see, the bulk of the key exchange work in TLS really occurs in the first three messages, “client hello”, “server hello”, and “client key exchange”. By the time the client is ready to send this last message, it already knows the encryption key. Hence it can start transmitting encrypted data right then, cutting a full roundtrip off the handshake. The rest of the handshake is just ‘mop-up’: mostly dedicated to ensuring that nobody tampered with the handshake messages in-flight.

If your reaction to the previous sentence was: ‘isn’t it kind of important to know that nobody tampered with the handshake messages?‘, you’ve twigged to the primary security objection to False Start. But we’ll come back to that in a moment.

False Start sounds awesome: why did Google yank it?

The problem with False Start is that there are many servers (most, actually) that don’t support it. The good news is that many of them will tolerate FS. That is, if the Client starts sending data early, they’ll hold onto the data until they’ve finished their side of the handshake.

But not every server is so flexible. A small percentage of the servers on the Internet — mostly SSL terminators, according to Langley — really couldn’t handle False Start. They basically threw up all over it.

Google knew about this before deploying FS in Chrome, and had taken what I will loosely refer to as the ‘nuke it from orbit squared‘ approach. They scanned the Internet to compile a blacklist list of IPs that didn’t handle False Start, and they shipped it with Chrome. In principle this should have done the job.

Unfortunately, it didn’t. It seems that the non-FS-compatible servers were non-compliant in a weird non-deterministic way. A bunch looked good when Google scanned them, but really weren’t. These slipped past Google’s scan, and ultimately Google gave up on dealing with them. False Start was withdrawn.

Ok, it has issues. But is it secure?

From my point of view this is the much more interesting question. A bunch of smart folks (and also: me) wasted last Friday afternoon discussing this on Twitter. The general consensus is that we don’t really know.

The crux of the discussion is the Server “finished” message (#8 in the diagram above). This message is not in TLS just for show: it contains a hash over all of the handshake messages received by the server. This allows the client to verify that no ‘man in the middle’ is tampering with handshake messages, and in normal TLS it’s supposed to verify this before it sends any sensitive data.

This kind of tampering isn’t theoretical. In the bad old days of SSL2, it was possible to quietly downgrade the ciphersuite negotiation so that the Browser & Server would use an ‘export-weakened’ 40-bit cipher even when both wanted to use 128-bit keys. Integrity checks (mostly) eliminate this kind of threat.

The FS designers were wise to this threat, so they include some mitigations to deal with it. From the spec:

Clients and servers MUST NOT use the False Start protocol modification in a handshake unless the cipher suite uses a symmetric cipher that is considered cryptographically strong … While an attacker can change handshake messages to force a downgrade to a less secure symmetric cipher than otherwise would have been chosen, this rule ensures that in such a downgrade attack no application data will be sent under an insecure symmetric cipher.

While this seems to deal with the obvious threats (‘let’s not use encryption at all!’), it’s not clear that FS handles every possible MITM threat that could come up. For example, there were a number of mitigations proposed to deal with the BEAST attack — from basic things like ‘don’t use TLS 1.0’ to ‘activate the empty-fragment’ protection. There’s some reason to be fearful that these protections could be overwhelmed or disabled by an attacker who can tamper with handshake messages.

Note that this does not mean that False Start was actually vulnerable to any of the above. The last thing I want to do is claim a specific vulnerability in FS. Or rather, if I had a specific, concrete vulnerability, I’d be blogging about it.

Rather, the concern here is that TLS has taken a long time to get to the point it is now — and we’re still finding bugs (like BEAST). When you rip out parts of the anti-tamper machinery, you’re basically creating a whole new world of opportunities for clever (or even not-so-clever) attacks on the protocol. And that’s what I worry about.

Hands off my NSS

There’s one last brief point I’d like to mention about False Start and Snap Start, and that has to do with the implementation. If you’ve ever spent time with the NSS or OpenSSL code, you know that these are some of the finest examples of security coding in the world.

Haha, I kid. They’re terrifying.

Every time Google adds another extension (Snap Start, False Start, etc.), NSS gets patched. This additional patch code is small, and it’s written by great coders — but even so, this patching adds new cases and complexity to an already very messy library. It would be relatively easy for a bug to slip into one of these patches, or even the intersection of two patches. And this could affect more than just Google users.

In summary

It may seem a little odd to spend a whole blog post on a protocol that’s already been withdrawn, but really: it’s worth it. Examining protocols like False Start is the only way we learn; and making TLS faster is definitely something we want to learn about. Second, it’s not like False Start is the last we’ll hear from the Google TLS crew. It’ll certainly help if we’re up-to-speed when they release “False Start II: False Start with a Vengeance”.

Finally, False Start isn’t really dead — not yet, anyway. It lives on in Chrome for conducting Next Protocol Negotiation (NPN) transactions, used to negotiate SPDY.

On a final note, let me just say that I’m mostly enthusiastic about the work that Google is doing (modulo a few reservations noted above). I hope to see it continue, though I would like to see it get a little bit more outside scrutiny. After all, even though Google’s primarily acting as its own test case, many people use Chrome and Google! If they get something wrong, it won’t just be Google doing the suffering.

Notes:

* With some notable exceptions: see this great presentation by Nate Lawson.