Attack of the week: XML Encryption

Unfortunately I had to skip this year’s CCS because I was traveling for work. This means I missed out on a chance to go to my favorite Chicago restaurant and on the architecture cruise. I’m told that there were also some research papers being given somewhere.

The Internet can’t make up for every missed opportunity, but it can help with the research. In fact, today’s news is all about one of those papers. I’m talking about Tibor Jager and Juraj Somorovsky’s work entitled “How To Break XML Encryption“.*

In case I had any doubts, it only took one glance at the first page to confirm that we’re back in “someone screwed up basic symmetric encryption” territory. But really, to describe Jager and Somorovsky’s findings like this does them no justice. It’s like comparing the time that kid built a nuclear reactor in his garage to, say, the incident at Fukushima.

Some background is in order.

What is XML Encryption and why should I care?

You probably already know that XML is the world’s most popular way to get structured data from point A to point B.** Following the success of HTML, the computing world decided that we needed a single “flexible” and ASCII-based format for handling arbitrary data types. (We’ve spent much of the subsequent period regretting this decision.)

The one upshot of this XML epidemic was the emergence of some standards and libraries, which — among other things — were supposed to help application developers process data in a reliable and secure way. One of those standards is SOAP, which is used to transport data in web services frameworks.

Another standard is the W3C XML Encryption Standard, which was dropped like a log in 2002 and doesn’t seem to have been updated since. The point of this standard was to give developers a uniform (and secure!) way to protect their XML documents so that we wouldn’t wind up with five thousand incompatible, insecure ways of doing it. (Oh the irony.)

Finally, a very common implementation of both standards can be found in the Apache Axis2 web services framework and in the RedHat JBoss framework. These are probably the most common open-source SOAP frameworks. They power a number of systems you don’t necessarily think about, but you probably should because they carry a lot of your personal information.

So what about the encryption?

To make a very long story short, the W3C standard recommends to encrypt messages using a block cipher configured using (our old friend) CBC-mode. Here’s a quick recap on CBC mode, courtesy Wikipedia:
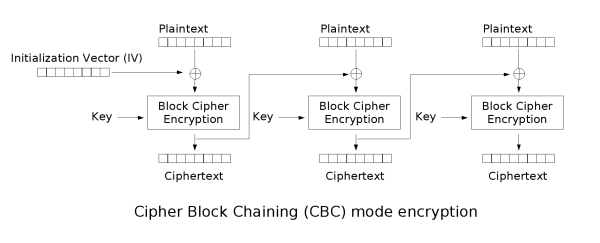
CBC mode encryption. The message is first subdivided into equal-length blocks and encrypted as in the diagram.  The circular plus symbol denotes XOR.

There are two basic things you need to know about CBC mode, and ought to know if you ever plan to use it.***

First: CBC requires that every plaintext be an even multiple of the block size. In the case of AES, this means 16 bytes. If the message is not the right length, then CBC implementations will pad the message with additional bytes. Of course it must be possible to recognize this padding so that it can be stripped off after decryption. There are various schemes for doing this.

The W3C standard uses the following padding approach. Let “MM” indicate message bytes, and let “NN” be the total number of padding bytes being added. “XX” represents arbitrary padding bytes, which can hold any value you want. A padded block will look like this:

0x MM MM MM MM MM MM MM MM MM MM XX XX XX XX XX NN
When a decryptor encounters a padded message, it looks at the last byte to figure out how many bytes to strip off. If it encounters padding that doesn’t make sense, i.e., NN > 16 or NN < 1, then it should see something funny going on and reject the message.
Second: CBC ciphertexts are malleable. This means that you can modify a CBC-encrypted ciphertext such that your modifications will carry through decryption, and have a meaningful effect on the resulting decrypted plaintext.
In the simplest case, you can truncate the message by stripping blocks off the end. This does the same thing to the resulting plaintext.
More interestingly, you can flip any bit (or set of bits) in the IV of a CBC-encrypted message, and upon decryption you’ll find that the same bits have been flipped in the first block of the decrypted plaintext. You can also do a lot more, but it’s not that important right now.

Anything else I should know?

Yup. You need to know how XML messages are formatted. They’re encoded using UTF-8 — essentially ASCII — with some special rules.

These are described in the paper. Briefly: any XML message that contains bytes ranging from 0x00-0x1F (with the exception of tabs, LF and CR) may be considered invalid. Similarly, the ampersand (&) character is used as an escape character, and must be followed by a valid string. Lastly, open brackets “<” must be properly closed. Messages that don’t meet this standard should be rejected.  ****
Of course, the message will have to be decrypted (using the appropriate key) before any of these checks can be run.

This is all fascinating, but how does it lead to an attack?

There’s one more detail I haven’t given you. You see, in addition to the details above, the Axis2 server (ditto JBoss) is kind enough to let you know when you haven’t met its standards for an XML message.

Specifically, after it decrypts a message, it kicks back an error if the message either: (1) has bad padding, or (2) contains invalid characters. In both cases, the error is the same. And this error is your way in the door.

I’m not going to completely describe the attack, but I’ll try to give an overview.

Imagine that you’ve intercepted a legitimately-encoded, encrypted XML message (IV, C1, …, CN) and you want to know what it says. You also have access to an Axis2 or JBoss server that knows the key and can decrypt it. The server won’t tell you what the message says, but it will give you an error if the encoding doesn’t meet its standards.

Sending the original, intercepted message won’t tell you much. We know that it’s encoded correctly. But what if you tamper with the message? This is precisely what Jager and Somorovsky proceed to do.

Step 1: Truncate the ciphertext. A good way to start is to chop off everything after the first ciphertext block, and send the much-shorter message consisting of (IV, C1) in to be decrypted. Chances are good that this new message will produce a decryption error, since the server will interpret the last byte of the decrypted message as padding — a number that should be between 0x01 and 0x10.

Step 2: Tweak the padding. I already said that if you flip bits in the IV, this will result in a similar change to the decrypted plaintext. Using this concept, you can force the last byte of the IV through all possible values and ask the server to decrypt each version of the ciphertext. More formally, the ‘new’ last IV byte can be computed as (‘original last IV byte’ ⊕ i) for i from 0 to 255.

In the best case, 16 of these test ciphertexts will decrypt without error. These correspond to the decrypted values 0x01 through 0x10, i,e., valid padding. If fewer than 16 of your test ciphertexts decrypt, this means that there’s something wrong with the message: probably it contains an unclosed “<” tag.

Step 3: Squish the bug(s). This is no problem. If exactly only one of your ciphertexts decrypts successfully, that means the open “<” character must in the first byte of the message. You caused the last byte of the message to decrypt to 0x10 (16 decimal), and the decryptor treated the whole block as padding. There are no errors in an empty message.

If two ciphertexts decrypt successfully, then the “<” character must be in the second position of the message, because now there are only two padding lengths (16 and 15) that would cause it to be stripped off. And so on. The number of successful decryptions tells you where the “<” is.

Now that you know where it is, kill it by flipping the last bit of the appropriate byte in the IV. This turns “<” into a harmless “=”.

Step 4: Learn the last byte of the block. You should now be able to come up with 16 test ciphertexts that decrypt successfully. This means you have 16 values of “i” such that ‘last byte of the original IV’ ⊕ i results in a successful decryption. One of these “i” values will differ from the others in the fourth most significant bit. This one will correspond to the padding value 0x10.

If “x” is the original plaintext byte and “i” is the value you just identified, you know now the last byte of the block. Since we have x ⊕ i = 0x10, then through the very sophisticated process of rearranging a simple equation we have 0x10 ⊕ i = x.

Now, using our knowledge of the last byte of the plaintext, manually tweak the IV so that the last byte (padding) of the plaintext will decrypt to 0x01.

Step 5: Learn everything else. The rest of the attack hinges on the fact that all of the bytes in the message should be ‘acceptable’ UTF-8 characters. Thanks to our trick with the IV, we can now flip arbitrary bits in any given byte, and see whether or not that leads to another ‘acceptable’ character or not.

Believe it or not, the results of this experiment tell us enough to figure out each character in turn. I won’t belabor this, because it takes a little bit of squinting at the ASCII table, but fundamentally there’s not much magic beyond that. It’s very simple and elegant, and it works.

Step 6: Finish it. You’ve done this for one block. Now do it for the rest. Just set your ‘ciphertext’ to be the next block in the message, and your ‘IV’ to be the ciphertext block immediately preceding it. Now go back to Step 1.

And that’s the ballgame.

Obviously all of this takes a lot of tests, which you can reduce a bit using some of the optimizations suggested in the paper. Jager and Somorovsky are able to recover plaintexts with “14 requests per plaintext byte on average.” But at the end of the day, who cares if it takes 50? The box is sitting there ready and willing to decrypt ciphertexts. And it’s incredibly unlikely that anyone is paying attention.

Ok. Can’t you fix this by authenticating the ciphertexts?

This entire attack is a special example of an adaptive chosen ciphertext attack. (Specifically, it’s a super-duper variation of Vaudenay’s padding oracle attack, which he discovered in 2002, the same year the W3C standard hit!)

These attacks can almost always be prevented with proper authentication of the ciphertexts. If the decryptor checks that the ciphertexts are valid before decrypting them, the attacker can’t tamper with them. Hence, no useful information should leak out to permit these attacks at all.

The designers could have added a mandatory MAC or even a signature on the ciphertext, or they could have used an authenticated mode of operation.

But the W3C standard does provide for MACs and signatures!

Indeed. As the authors point out, there’s an optional field in the specification where you can add a signature or a MAC over the ciphertext and its meta data. But there’s one tiny, hilarious thing about that signature…

Did I mention it’s optional?

You can quite easily take a signed/MACed ciphertext and ‘convert’ it into one that’s not signed or MACed at all, simply by stripping the ciphertext contents out and placing them into a section that does not claim to have a signature. Since the spec doesn’t mandate that the authentication be on every message, the decryptor will be totally cool with this.

So in summary: optional MACs and signatures don’t buy you much.

Is there anything else to say about this?

Lots. Stop using unauthenticated CBC mode. Stop using any encryption standard designed before 2003 that hasn’t been carefully analyzed and recently updated. Stop using any unauthenticated encryption at all. Wrap your SOAP connections with TLS (a recent version!) if you can.

People didn’t really think much about active chosen ciphertext attacks on symmetric encryption before 2000, but now they’re the new hip thing. If your system is online and doesn’t have a solid, well-analyzed protection against them, don’t pretend that you’re doing anything at all to secure your data.

I wish I had a funny, pithy way to sum this all up. But honestly, I’m just a little depressed. It’s not Jager and Somorosky’s fault at all — this is a great paper. It’s just that there’s too much embarrassingly bad crypto going around.

While I love reading these papers, I’m starting to feel that this one-off approach is not sufficient to the problem. Maybe what the community needs is a centralized clearinghouse for this stuff, a website where suspect crypto standards (and implementations) can be identified and listed. Crowdsourced and analyzed. Probably many are just fine, but I doubt most have been looked at (or even thought about in a while).

Anyone looking for a project?

Notes:
  
* Tibor Jager and Juraj Somorovsky, “How To Break XML Encryption”. In ACM CCS 2011. ACM Press.

** Someone is inevitably going to tell me that JSON is the world’s most popular way to move structured data. Ok. I don’t care.

*** But better yet, don’t use it. Use a standard authenticated encryption scheme like CCM, OCB or GCM, and use someone else’s implementation according to the standards. These modes should prevent all of this nonsense.

**** These details are quoted straight from the Jager and Somorovsky paper. I’m not 100% sure if all implementations enforce this, but Axis2 does.
DESFire

If you skipped today’s crypto news, you missed some good press for Daviddesfire Oswald and Christof Paar’s recent side-channel attack on the Mifare DESFire MF3ICD40 chip.* I’m hardly an expert on side-channel attacks, but being uninformed has never stopped me before, and I figured it might be fun to read the paper and talk about this very neat attack.

What’s the DESFire MF3ICD40 and where is it used?

I’m guessing MF3ICD40 probably isn’t a household name where you live, but you might be familiar with one of the systems that use it.  These include the San Francisco Clipper card, the Czech “in-karta”, and a cute Australian card transit card known as the myki.  It also powers a number of access control systems, like the prox cards that let you into some high security buildings.
Clipper card.

The MF3ICD40, henceforth “MF3”, is a capable little chip.  It’s a Radio Frequency Identification (RFID) device, meaning that it communicates wirelessly with a reader — e.g., a Clipper card turnstyle.  It can store a certain amount of information and retrieve it on demand.  Like the DST chip I mentioned in an earlier post, every MF3 contains a cryptographic key and a cipher, which it can use to (among other things) perform a challenge/response authentication protocol.

Unlike the DST, the MF3 uses a pretty reasonable cipher for its authentication protocol. Specifically, it employs Triple-DES with a 112-bit key.  While 3DES is definitely getting a bit long in the tooth (it’s been deprecated in FIPS), it’s not thought to be vulnerable to any truly practical attacks.  Nor, to the best of my knowledge, is there anything wrong with the way that the MF3 uses 3DES.

So if the crypto is ok, what’s the problem?

Just like the DST, the MF3 chip contains no internal power source.  Instead, power for the chip is extracted from a magnetic field generated by the reader.  This is mostly a good thing — by powering the chip this way, the designers were able to dramatically reduce its size and cost.  Moreover, you don’t need to replace your MF3 when some crappy battery dies.

Unfortunately, the use of an external power source opens the device up to a special class of side-channel attack known as Correlation Power Analysis, or CPA.  Since the MF3 draws power from the reader, a malicious reader can actually tell — from moment to moment — how much power the device is using.

Ordinarily this wouldn’t be very interesting. However, if you know exactly how the device performs the computation, and you can repeatedly measure the device’s power consumption while sending it carefully crafted input values, you can actually learn quite a lot.  Specifically, when the device encrypts (or decrypts) your chosen inputs, those power fluctuations can actually leak the bits of the cryptographic key.  In the case of MF3, you can obtain the full 112-bit key in about seven hours.

Isn’t side channel analysis pretty well known?

Yes, and that’s what makes this interesting.  With caveats.

Side channel attacks themselves are hardly a new thing.  The concept of using power analysis to attack cipher implementations was first proposed in CRYPTO ’99 by Paul Kocher, Joshua Jaffe and Benjamin Jun, all of whom worked for Paul’s company, Cryptography Research.  In a truly inspired move, Paul and his researchers turned around and patented the standard set of countermeasures to the very attack they had invented.  These countermeasures can be found in just about every high-security smart card manufactured today.

This story is important because the MF3 clearly didn’t have the latest and greatest hardware countermeasures built into it.  If it had, the Oswald and Paar attacks wouldn’t have gone anywhere. (Though interestingly, it did have one countermeasure, see below.)

This seems to be a common situation for a certain class of RFID devices, of which the MF3 is one.  These devices toe a funny line between “contactless smart card” (where SCA countermeasures would be expected) and “plain-old RFID” where security isn’t thought to be as important. Unfortunately, the people who select these systems may not realize this, and that’s when bad things can happen.

I should also add that — unlike a recent side-channel attack on KeeLoq — this attack does not require the adversary to physically crack open the device. It’s implemented purely via the EM field.

So how does the attack work?

This is clearly the crux of the matter, and unfortunately this is where I’m going to have to let you off with a warning.  Side channel analysis is just not my area, and there’s little I can offer here that would improve on reading the paper itself.**, ***

But to make a very short go of it, DES works by breaking the key up into smaller pieces called “subkeys”, each of which is used in a different round of the cipher.  Portions of these subkeys are combined with bits of of an attacker-supplied input and sent to a series of small functions called S-boxes.  Since only a few bits go into each S-box, there is a relatively small set of possible input values, each of which results in a slightly different power consumption profile.

By observing the power consumed when calculating these S-boxes on different inputs — both for known and unknown keys, and over many, many experiments — the attacker can correlate these traces to figure out the bits that come from an unknown key.  The full key recovery attack takes ~250,000 traces, which require about 7 hours to collect.

The most interesting aspect of the paper is that the authors didn’t actually know how the DES implementation in the MF3 worked.  Much of the paper is devoted to reverse-engineering the necessary details of the operation by examining power traces.  What’s most interesting about this discussion is that along the way, they discovered that the MF3 actually does implement a countermeasure to CPA — specifically, it randomly adds up to eight “dummy rounds” to DES. Unfortunately for the MF3, this protection was not sufficient to prevent the attack.

Figure from the Oswald-Paar paper.  These charts show the operation of the DES cipher  on several input values.  The authors used this information to reverse-engineer the operation of the device.

So what’s next for MF3?

A quick glance at the MF3 website will tell you that the manufacturer “has begun phasing out the MF3ICD40”, but that “orders … will continue to be taken until December 31st, so start planning your new year’s party now!” (Ok, I made up the last bit.) From here on out, it looks like it’s going to be AES-based cards all the way.

The note doesn’t specifically mention this attack, but I assume that’s what’s behind it.  If so, that’s a pretty good response for a manufacturer.  To pull a profitable card off of the market probably cost them quite a bit, but it protects their reputation, not to mention their customers.  Unfortunately, there’s no indication that the newer AES-based cards actually have stronger protections against side channel analysis; they’re just using a different cipher.  But I guess that’s what next year’s CHES is for.

Notes:

* This post brought to you by David Oswald and Christof Paar.  Breaking Mifare DESFire MF3ICD40: Power Analysis and Templates in the Real World.  In CHES ’11.

** This is an extended version of the conference paper that I read. Thanks to Bart Coppens for finding the link.

*** If you want to hear from people who do know their side channels, see Luke Mather’s excellent post on DPA and distinguishers from the Bristol Cryptography Blog.

A diversion: BEAST Attack on TLS/SSL Encryption

Update 9/22/11: It appears that OpenSSL may have actually written a patch for the problem I describe below, all the way back in 0.9.6d (2002), so this attack may not be relevant to OpenSSL systems.  But I haven’t reviewed the OpenSSL code to verify this.  More on the patch at the bottom of this post.

Update 10/2/11: Yes, the attack works pretty much as described below (and see comments).  To advise future standards committees considering non-standard crypto, I have also prepared this helpful flowchart.

There’s some news going around about a successful attack on web browsers (and servers) that support TLS version 1.0.  Since this is ostensibly a blog, I figured this subject might be good for a little bit of real-world speculation.

My first thought is that “attacks” on TLS and SSL need to be taken with a grain of salt.  The protocol has been around for a long time, and new attacks typically fall into one of two categories: either they work around SSL altogether (e.g., tricking someone into not using SSL, or going to an untrusted site), or they operate on some obscure, little-used feature of SSL.

(Please don’t take this as criticism of the attacks I link to above.  At this point, any attack against TLS/SSL is a big deal, and those are legitimate vulnerabilities.  I’m trying to make a point about the strength of the protocol.)

This attack is by researchers Juliano Rizzo and Thai Duong, and if we’re to believe the press, it’s a bit more serious than usual.  Ostensibly it allows a man-in-the-middle to decrypt HTTPS-protected session cookies, simply by injecting a little bit of Javascript into the user’s web browser.  Since we’re constantly running third-party Javascript due to web advertising, this might not be a totally unrealistic scenario.

The attack is claimed to make use of a theoretical vulnerability present in all versions of SSL and TLS 1.0 (but not later versions of TLS).  Unfortunately there are few details in the news reports, so until the researchers present their findings on Friday, we have to rely on some educated guesses.  And thus, here’s a big caveat:

Every single thing I write below may be wrong!

What the heck is a Blockwise-Adaptive Chosen Plaintext Attack?

Based on a quick Google search, the attack may be based a paper written by Gregory Bard at the University of Maryland.  The basic idea of this attack is that it exploits the particular way that TLS encrypts long messages using block ciphers.  To do this, Bard proposes using Javascript.

Besides being incredibly annoying, Javascript is a huge potential security hole for most web browsers.  This is mostly mitigated in browsers, which place tight restrictions on the sorts of things that a Javascript program can do.  In terms of network communication, Javascript programs can barely do anything.  About the only exception to this rule is that they can communicate back to the server from which they were served.  If the page is HTTPS-protected, then communication gets bundled under the same TLS communication session used to secure the rest of the web page.

In practice, this means that any data sent by the Javascript program gets encrypted under the same key that is also used to ship sensitive data (e.g., cookies) up from the web browser to the server.  Thus, the adversary now has a way to encrypt any message she wants, under a key that matters.  All she has to do is sneak a Javascript program onto the user’s web page, then somehow intercept the encrypted data sent to the server by the browser.  This type of thing is known as a chosen plaintext attack.

Normally chosen plaintext attacks are not a big deal.  In fact, most encryption schemes are explicitly designed to deal with them.  But here is where things get interesting.

TLS 1.0 uses a block cipher to encrypt data, and arranges its use of the cipher using a variant of the Cipher Block Chaining mode of operation.  CBC mode is essentially a means of encrypting long messages using a cipher that only encrypts short, fixed-size blocks.

CBC mode encryption (diagram: Wikipedia).  The circular cross denotes the XOR operation.  The message is first divided into even-sized blocks.  A random Initialization Vector (IV) is used for the first block.  Each subsequent block is “chained” to the message by XORing the next block of plaintext with the previous block of ciphertext.

CBC mode encryption is illustrated above.  Note that it uses a block cipher as an ingredient.  It also depends on a random per-message nonce called an Initialization Vector, or IV for short.

If you asked me to describe the security properties of CBC, I would recite the following mantra: as long as you use a secure block cipher, and as long as you generate a new, random IV for each message, this mode is very secure against eavesdroppers — even when the adversary can obtain the encryption of chosen plaintexts.  If you doubted me, I would point you here for a formal proof.

You may have noticed that I emphasized the phrase “as long as”.  This caveat turns out to be important.

In the implementation of CBC mode, the TLS designers made one, tiny optimization.  Rather than generating a fresh IV for each message, the protocol re-uses the last block of the previous ciphertext message that was sent.  This value becomes the IV for the new message.

In practice, this tiny modification has huge implications.  If we assume that the adversary — let’s call her Sue — is sniffing the encrypted data sent by the browser, then she can obtain the IV that will be used for the next message.  Now let’s say she has also identified a different block of ciphertext C that she wants to decrypt, maybe because it contains the session cookie.  While she’s at it, she can easily obtain the block of ciphertext C’ that immediately precedes C.

None of this requires more than simple eavesdropping.  Sue doesn’t know what message C encrypts — that value, which we’ll call M, is what she wants to learn — but she does know that C can be expressed using the CBC encryption formula as:

      C = AES-ENC(key, M ⊕ C’)

Sue also knows that she can get her Javascript program to transmit any chosen block of data M* that she wants.  If she does that, it will produce a ciphertext C* that she can sniff.

Now let’s make one more huge assumption.  Imagine that Sue has a few guesses for what that unknown value of M might be.  It’s 16 bytes long, but maybe it only contains a couple of bytes worth of unknown data, such as a short PIN number.  If Sue generates her value M* based on one of those guesses, she can confirm whether C actually encrypts that value.

To cut through a lot of nonsense, let’s say that she guesses M correctly.  Then she’ll generate M* as:

M* = IV ⊕ M ⊕ C’

When her Javascript program sends out M* to be encrypted, the TLS layer will encrypt it as:

C* = AES-ENC(key, IV ⊕ M*) =                       (which we can re-write as…)
AES-ENC(key, IV ⊕ IV ⊕ M ⊕ C’ ) =      (and XORing cancels…)
AES-ENC(key, M ⊕ C’)

All I’ve done above is write out the components of M* in long form, and simplify the equation based on the fact that the IV ⊕ IV term cancels out (a nice property of XOR).  The important thing to notice is that if Sue guessed correctly, the ciphertext C* that comes out of the browser will be identical to the captured ciphertext C she wants to decrypt!  If she guessed wrong, it won’t.

So assuming that Sue has time on her hands, and that there are only a few guesses, she can repeat this technique over and over again until she figures out the actual value of M.

But this guessing stuff is crazy!

If you’re paying attention, you’ll already have twigged to the one huge problem with this attack.  Yes, it works.  But it only works if she has a small number of guesses for the value M.  But in practice, M is 16 bytes long.  If she somehow knows the value of all but two bytes of that value, she might be able to guess the remaining bytes in about 2^15 (32,768) attempts on average.  But in the more likely case that she doesn’t know any of the plaintext, she has to try on average about 2^127 possible values.

In other words, she’ll be guessing until the sun goes out.

Let’s get aligned

And this is where the cleverness comes in.  I don’t know exactly what Rizzo and Duong did, but the paper by Bard hints at the answer.  Recall that when the browser encrypts a CBC-mode message, the first step is to chop the message into equal-length blocks.  If it’s using AES, these will each be 16 bytes long.

If Sue needs to guess the full contents of a random 16-byte block, she’s hosed — there are too many possibilities.  The only way this technique works in general is if she knows most of a given block, but not all of it.

But what if Sue could convince the browser to align the TLS messages in a manner that’s useful to her?  For example, she could fix things so that when the browser sends the cookie to the server, the cookie would be pre-pended with something that she knows — say, a fixed 15-byte padding.  That would mean that the stuff she wants to learn — the start of the cookie — takes up only the last byte of the block.

If Sue knows the padding, all she has to guess is the last byte.  A mere 256 possible guesses!

Now what if she can repeat this trick, but this time using a 14-byte known padding. The block would now end with two bytes of the cookie, the first of which she already knows. So again, 256 more guesses and she now knows two bytes of the cookie!  Rinse, repeat.

This technique could be quite effective, but notice that it relies on some strong assumptions about the way Sue can get the browser to format the data it sends.  Does the Rizzo and Duong attack do this?  I have absolutely no idea.  But based on my understanding of the attack and the descriptions I’ve read, it represents my best speculation.

I guess pretty soon we’ll all know how good I am at guessing.

Update 9/22/11: This post by James Yonan offers the first piece of confirmation suggesting that BEAST is based on the Bard attack.  Yonan also points out that OpenSSL has included a “patch” to defend against this issue, all the way back to version 0.9.6d (2002).  In a nutshell, the OpenSSL fix encrypts random message fragments at the start of each new message sent to the server.  This additional message fragment works like an IV, ensuring that M* is no longer structured as I describe above.  Yonan also notes that NSS very recently added a similar patch, which indicates that NSS-based browsers were the problem (this includes Firefox, Chrome).

I’m usually critical of OpenSSL for being a code nightmare.  But (pending verification) I have to give those guys a lot of credit for this one.